
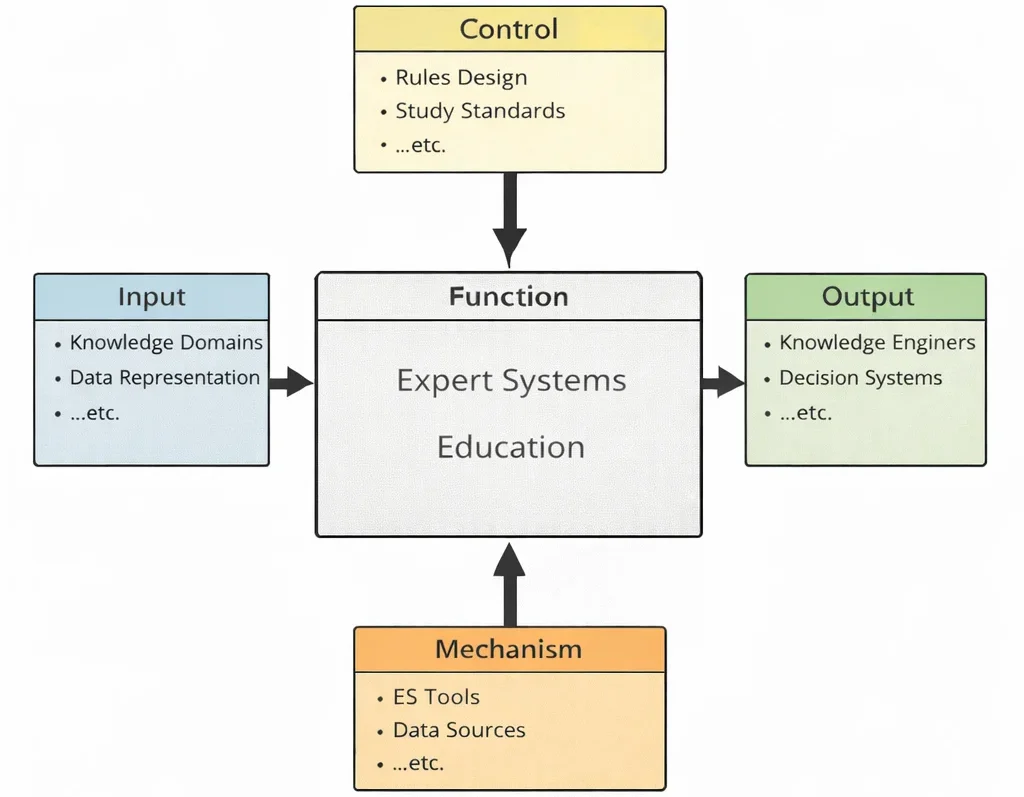
Artificial Intelligence & Machine Learning Topic Hub
Key Components of Expert Systems
Knowledge Base
- The repository of domain-specific knowledge.
- Contains facts, heuristics (rules of thumb), and structured data to support problem-solving.
- Example: In a medical diagnosis system, the knowledge base may include symptoms, diseases, and treatment options.
Inference Engine
- The reasoning mechanism that applies logical rules to the knowledge base to draw conclusions.
- Uses techniques like forward chaining (data-driven) and backward chaining (goal-driven) to arrive at solutions.
User Interface
- The interface through which users interact with the expert system.
- Allows users to input data, receive recommendations, and understand the reasoning behind decisions.
Reasoning Under Uncertainty in Expert Systems
1) Certainty Factors (CF) — Pragmatic & Fast
Popularized in MYCIN, a certainty factor is a number in the interval [-1, +1] attaching support (positive) or refutation (negative) to a hypothesis H given evidence E: CF(H | E). Rules produce CFs; multiple pieces of evidence are merged with simple algebra.
Typical CF Combination Rules (MYCIN-Style)
- If both CFs support H (both > 0):
CFcomb = CF1 + CF2 × (1 – CF1)
- If both CFs refute H (both < 0):
CFcomb = CF1 + CF2 × (1 + CF1)
- If one supports and one refutes:
CFcomb = (CF+ + CF–) / (1 – min(|CF+|, |CF–|))
These formulas are fast, monotone, and easy to debug—great for rule-based diagnostics and advisory systems.
Worked Mini-Example (Certainty Factors)
- Rule 1: If cough & fever then flu (rule strength = 0.9). Observed: cough = 0.8, fever = 0.6 ⇒ evidence CF ≈ min(0.8, 0.6) × 0.9 = 0.54.
- Rule 2: If rapid test positive then flu (0.7). Observed: test positive ⇒ CF = 0.7.
Combine (both positive): 0.54 + 0.7 × (1 – 0.54) = 0.862.
Interpretation: Strong, but not absolute, belief in “flu”.
2) Bayesian Updating — Probabilistic & Principled
When you have (or can estimate) likelihoods and priors, Bayes’ rule offers a coherent update:
$$P(H \mid E) = \frac{P(E \mid H) P(H)}{P(E \mid H) P(H) + P(E \mid \neg H) P(\neg H)}$$
Odds Form (Numerically Stable):
$$\frac{P(H \mid E)}{P(\neg H \mid E)} = \frac{P(H)}{P(\neg H)} \times \frac{P(E \mid H)}{P(E \mid \neg H)}$$
Toy Example (Bayesian Update)
Prior P(H) = 0.1. Test: P(E | H) = 0.9, P(E | ¬H) = 0.2.
Then P(H | E) = (0.9 × 0.1) / (0.9 × 0.1 + 0.2 × 0.9) = 0.09 / (0.09 + 0.18) ≈ 0.333.
Positive evidence raises belief from 10% to 33%.
3) Dempster–Shafer (Evidence Theory) — Modeling Ignorance Explicitly
Instead of point probabilities for every hypothesis, assign basic belief mass m(•) over sets (including the whole frame Θ). Belief Bel(A) and Plausibility Pl(A) bound your support:
$$\text{Bel}(A) = \sum_{B \subseteq A} m(B), \qquad \text{Pl}(A) = \sum_{B \cap A \neq \emptyset} m(B)$$
Independent evidence pools via Dempster’s rule:
$$m_{12}(A) = \frac{1}{1 – K} \sum_{B \cap C = A} m_1(B) m_2(C), \qquad K = \sum_{B \cap C = \emptyset} m_1(B) m_2(C)$$
Mini Example (Dempster–Shafer)
Frame Θ = {flu, cold}.
Sensor 1: m1({flu}) = 0.5, m1(Θ) = 0.5.
Sensor 2: m2({flu}) = 0.6, m2(Θ) = 0.4.
No conflict K = 0. Then m12({flu}) = 0.5 × 0.6 + 0.5 × 0.6 + 0.5 × 0.4 = 0.8 (rest on Θ).
So Bel(flu) = 0.8, Pl(flu) = 1.0.
4) Fuzzy Logic Rules — Handle Vagueness, Not Randomness
Fuzzy sets attach a degree of membership μ ∈ [0, 1] to continuous concepts like “high fever.” Rules fire with partial truth; common AND is min(•, •) (or product).
Example (Mamdani-Style)
Rule: “IF fever is high AND cough is strong THEN flu is likely.”
Suppose μfever(38.2°C) = 0.7, μcough = 0.8.
Antecedent truth α = min(0.7, 0.8) = 0.7.
Clip the output membership for “flu likely” at 0.7 and defuzzify (e.g., centroid) if a crisp score is needed.
5) Which to Use When?
- Certainty Factors: Small/medium rule-bases; quick, interpretable heuristics; no ground-truth likelihoods available.
- Bayesian: You can estimate P(E | H) or learn them; need calibrated probabilities and principled decision theory.
- Dempster–Shafer: Multiple weak/heterogeneous sources; want to represent ignorance explicitly and postpone hard commitments.
- Fuzzy Logic: Variables are vague/graded (e.g., “high”, “warm”); need smooth rule-based control or explanations for non-stochastic ambiguity.
• Make rule semantics explicit (sign of CFs, independence assumptions, membership definitions).
• Unit-test algebra (CF combiner, Bayes odds, DS conflict K, fuzzy t-norm/defuzzifier).
• Log intermediate numbers for explainability; plot how conclusions change as evidence varies.
Inference Strategies & Control
1) Forward vs. Backward Chaining
| Inference Paradigm | Mechanism & Direction | Trace Example | Best Applied To |
|---|---|---|---|
| Forward Chaining (Data-driven) | Start from known facts; match rule antecedents; fire rules to produce new facts. Stops when no new rules fire or goal is reached. | Facts: fever, cough, recent_contactR1: IF fever & cough THEN likely_fluR2: IF likely_flu & recent_contact THEN recommend_test | Monitoring/control, configuration, real-time sensor streams. |
| Backward Chaining (Goal-driven) | Start from a query/goal; look for rules that conclude it; prove their premises recursively. Asks user for missing facts. | Goal: pneumoniaR7: IF infiltrate_on_xray & high_fever THEN pneumonia.Prove sub-goal infiltrate_on_xray (ask user); then prove high_fever. | Diagnostic Q&A sessions, medical troubleshooting, legal audits. |
2) Working Memory, Production Memory, & Agenda
- Working Memory (WM): Current facts and assertions (may include CFs, timestamps, and data sources).
- Production Memory: The rule base containing IF–THEN productions.
- Agenda: The current set of conflicting eligible rules; conflict resolution chooses one to fire.
3) Conflict Resolution (How to Pick the Next Rule)
- Specificity: Prefer rules with more conditions (more specific explanations).
- Rule Priority / Salience: Explicit numeric priority breaks ties and encodes domain policy.
- Recency (LIFO): Prefer rules using the most recently added facts to keep reasoning focused.
- Refraction: Prevent the same rule from firing repeatedly on the same fact bindings.
- Meta-rules: Domain heuristics (e.g., “never override a certain diagnosis with a tentative one”).
4) The RETE Idea (Fast Pattern Matching)
RETE compiles the rule conditions into a shared network so repeated matching is avoided:
- Alpha Nodes: Test a single condition (e.g.,
(symptom fever)); cache passing facts. - Beta Nodes (Joins): Combine partial matches (e.g., facts that share the same patient ID).
- Tokens / Memories: Incremental updates flow only where needed when Working Memory changes.
- Benefits: Avoids re-checking every rule against all facts; scales well for large rule sets.
5) Looping & Halting
- Define halting criteria: goal reached, no activations left, or step/time/activation budget exhausted.
- Use refraction and state guards (e.g., only assert a fact once; or assert with version/time).
- Detect cycles in backward chaining (memoize failed sub-goals; avoid revisiting identical states).
6) Small, End-to-End Example (Forward Chaining Trace)
Rules:
• R1: IF fever & cough THEN likely_flu (salience 10)
• R2: IF likely_flu & recent_contact THEN recommend_test (salience 9)
• R3: IF likely_flu & elderly THEN priority_care (salience 9)
Initial Working Memory: fever, cough, recent_contact
Agenda Policy: Highest salience first, then specificity, then recency; refraction enabled.
Execution Trace:
1. Match R1 ⇒ fire ⇒ add likely_flu to Working Memory.
2. Match R2 and R3; R2 & R3 tie on salience; specificity/recency break tie → fire R2 ⇒ add recommend_test.
3. R3 is eligible but elderly is absent ⇒ no fire. Agenda empty ⇒ halt.
7) Practical Engineering Tips
- Keep facts normalized: Consistent keys/slots (e.g., patient ID, timestamp, source) make joins robust.
- Prefer additive facts over destructive updates: Keep provenance; allow explanation to “show its work.”
- Modularize rules: Group by sub-goals; keep rule antecedents short and readable.
- Explainability: Log “fired rule”, used facts, and resulting assertions for every step.
- Test harness: Snapshot Working Memory before/after; create golden traces; unit-test conflict resolution choices.
Explanation & Justification Facilities
1) Core Explanation Types
- Why? (Justification): Shows the fired rule(s) and the specific facts that satisfied antecedents. Includes certainty/weights and natural-language paraphrases.
- How? (Derivation Trace): A step-by-step rule-firing trace from initial facts to conclusion. Useful for audits and training.
- Why-Not? (Missing Evidence): Lists rules that could have concluded the goal but failed, showing which antecedents were unknown/false and how to satisfy them.
- How-To? (Goal Reduction): Backward-chaining view displaying subgoals that must be proven to reach the target, including alternative rule paths.
2) Trace vs. Summary
- Executive Summary: 1–3 sentences with the main rule(s), net confidence, and key evidence.
- Expandable Trace: Chronological list of rule firings with inputs/outputs.
- Evidence Table: Facts, values, time, source, confidence, and whether each was consumed.
3) Example Derivation Log & Evidence Table
Summary Conclusion: recommend_test (CF 0.78). Fired R1 (fever & cough ⇒ likely_flu; CF 0.62) and R2 (likely_flu & recent_contact ⇒ recommend_test; CF 0.78).
Show Full Trace & Evidence Table
• WM0: fever(0.8, src=thermometer), cough(0.7, src=self-report), recent_contact(1.0, src=survey)
• R1 fires → assert likely_flu(0.62)
• R2 fires → assert recommend_test(0.78)
{
  "fever": { "value": true, "cf": 0.80, "source": "thermometer", "time": "t0" },
  "cough": { "value": true, "cf": 0.70, "source": "self_report", "time": "t0" },
  "recent_contact": { "value": true, "cf": 1.00, "source": "survey", "time": "t0" },
  "likely_flu": { "derived_by": "R1", "cf": 0.62, "time": "t1" },
  "recommend_test": { "derived_by": "R2", "cf": 0.78, "time": "t2" }
}
4) “Why-Not” Counterfactual Example
Goal Failed: pneumonia not concluded.
• Rule R7 requires infiltrate_on_xray & high_fever.
• high_fever was satisfied (0.82); infiltrate_on_xray was missing.
• Next Recommended Action: Order chest X-ray or import imaging report.
5) Minimal Logging Schema for Compliance Audits
{
  "case_id": "12345",
  "conclusion": { "symbol": "recommend_test", "cf": 0.78 },
  "trace": [
    { "rule": "R1", "inputs": ["fever", "cough"], "output": "likely_flu", "cf_out": 0.62 },
    { "rule": "R2", "inputs": ["likely_flu", "recent_contact"], "output": "recommend_test", "cf_out": 0.78 }
  ],
  "evidence": {
    "fever": { "cf": 0.80, "source": "thermometer", "time": "2026-01-01T10:15Z" },
    "cough": { "cf": 0.70, "source": "self_report", "time": "2026-01-01T10:10Z" },
    "recent_contact": { "cf": 1.00, "source": "survey", "time": "2026-01-01T09:55Z" }
  }
}
Knowledge Acquisition & Maintenance
1) Eliciting Knowledge from Subject-Matter Experts (SMEs)
- Structured Interviews: Enumerate goals, inputs, exceptions, and “never do X” constraints.
- Think-Aloud Protocols: SMEs solve real cases while narrating decisions to capture thresholds and conditions.
- Card Sorting / Decision Ladders: Group signals into higher-level concepts to uncover intermediate hypotheses.
- Counter-Examples: Collect failure modes and edge cases to prevent over-generalized rules.
2) Canonical Fact Schema
{
  "subject": "patient:1234",
  "predicate": "vital.sign.temperature",
  "value": 38.2,
  "unit": "C",
  "time": "t0",
  "source": "thermometer",
  "confidence": 0.90,
  "provenance": { "method": "sensor_ingest", "version": "v3.1" }
}
3) Rule Templates & Decision Tables
# Production Rule Template (CF-Style)
RULE R1:
    IF fever(temp >= 38.0, cf >= 0.7) AND cough(present = True, cf >= 0.6)
    THEN likely_flu(cf = combine(0.8, inputs))
BECAUSE "Fever + cough strongly indicate flu."| Fever | Cough | Recent Contact | Conclusion | Confidence |
|---|---|---|---|---|
| High | Present | True | recommend_test | 0.80 |
| High | Present | False | likely_flu | 0.60 |
| Low | Absent | — | no_action | 1.00 |
4) Validation, Consistency & KB Testing
- Redundancy/Subsumption: Detect rules whose antecedents imply others; merge or prioritize.
- Conflicts: Flag rules that assert opposite conclusions under overlapping conditions.
- Golden Cases: Curate representative cases with expected conclusions & confidences to run on every change.
- Mutation Tests: Perturb inputs (± thresholds, missing facts) to check stability and graceful degradation.
Download SME Interview Worksheet
A printable, multi-page worksheet to structure knowledge acquisition sessions with subject-matter experts.
Neuro-Symbolic & Hybrid Expert Systems (Rules + ML)
1) Integration Patterns
- ML → Facts (Feature/Finding Extraction): Run ML first; convert outputs into facts with confidence, then reason with rules.
if ml.spam_prob >= 0.85:
assert Fact("email.spam", True, confidence=ml.spam_prob) - Rules → ML (Gating & Post-Filters): Rules decide when to call ML and how to interpret results.
IF channel == "web" AND size < 5MB THEN run_model("doc_classifier")
IF doc.class == "policy" AND confidence < 0.70 THEN require_review = True - Co-Decision / Adjudication: Rules and ML both propose conclusions; a meta-policy adjudicates conflicts.
IF rule_outcome == "deny" AND ml_outcome == "allow" AND risk == "high" THEN final = "deny"
2) Confidence & Calibration Threshold Policy
| Calibrated Probability p | Certainty Factor (2p – 1) | Action Policy |
|---|---|---|
| ≥ 0.90 | ≥ 0.80 | Auto-approve (if no rule blocks) |
| 0.60 – 0.89 | 0.20 – 0.78 | Require human review |
| < 0.60 | < 0.20 | Do not act / Ignore |
Case Studies & Design Patterns
Case Studies
- Medical Triage (Forward Chaining + Guardrails): Vitals and symptoms enter as facts; ML detects pneumonia risk p from X-rays; rules enforce immediate escalation if SpO2 < 90%.
- Credit Policy (Goal-Driven + Decision Tables): KYC rules gate eligibility → calibrated ML risk score → decision table maps score bands and policy overrides to final approval/decline actions.
- Industrial QA (Vision ML + Rule Containment): Camera feeds classify defects; rules monitor a rolling window (e.g., 3 defects in last 10 parts) to automatically stop assembly lines.
- Support Triage (NLP Intents + Compliance Rules): NLP classifies customer intents, while compliance rules redact PII and route tickets to secure queues.
Design Patterns Summary
| Pattern | When to Use | How it Works | Watch-outs |
|---|---|---|---|
| Guardrails-First | Safety/compliance is paramount | Rules run before/after ML; deny/review policies bound outcomes | Document precedence; avoid silent overrides |
| ML → Facts | Unstructured text/vision data | Normalize model outputs as facts with confidence & version | Calibrate scores; log provenance for audits |
| Rules → ML (Gating) | Control cost & latency | Rules decide when to invoke models; post-filters evaluate results | Don’t starve ML of necessary context |
| Adjudication | Rules and ML disagree | Meta-policy resolves conflicts by risk, confidence, and utility | Test boundary cases; log rationale |
Performance Tuning & Debug Quick Reference
| Symptom | Suspect Causes | Fast Checks | Engineering Fixes |
|---|---|---|---|
| Latency Spikes (p95/p99) | I/O in rule loop, agenda thrash, GC pauses | Check max activations per cycle & external calls in rule actions | Move I/O out of loop; stage inputs before reasoning; cap max activations. |
| Agenda Explosion | Missing refraction, broad rule conditions | Check for repeated firings on identical fact bindings | Enable refraction; split giant rules; push selective predicates earlier. |
| Working Memory Bloat | Unretracted transient facts, no TTL | Monitor facts per case over time | Add TTL expirations; retract consumed temporaries; scope Working Memory per case. |
| Rule Re-Firing Loops | Cyclic dependencies, re-asserting same facts | Check trace for repeating A ⇒ B and B ⇒ A cycles | Add status guards; store previous state; break cycles with halting conditions. |
# Minimal Debug Loop Script
# 1. Reproduce with golden case trace
run_case(rules="v3.2", case="GC-017", trace=True)

# 2. Snapshot RETE & Agenda metrics
metrics = dump_metrics(rete=True, agenda=True, wm=True)

# 3. Apply fix and re-benchmark
benchmark(cases="golden.csv", iters=200, concurrency=4)
Applications, Benefits, & Limitations of Expert Systems
Core Applications
- Medical Diagnosis (MYCIN, Watson Health): Analyzes clinical history and lab flags to suggest bacterial infection treatments and cancer therapies.
- Financial Advice & Risk Assessment (FICO, Robo-Advisors): Evaluates credit data, automates loan approvals, and executes portfolio rebalancing.
- Complex Engineering Solvers (XCON, CAD Expert Systems): Configures computer system hardware and diagnoses industrial assembly failures.
- Legal, Agriculture, Education & Environment: Legal research (ROSS), crop pest management, intelligent tutoring systems, and water quality monitoring.
Benefits vs. Limitations
Limitations: Domain specificity (cannot adapt outside knowledge base), lack of creative problem-solving, and maintenance overhead (“knowledge engineering bottleneck”).
Why Study Expert Systems
2. Exploring Rule-Based Logic & Knowledge Representation: Learning “if-then” rules, certainty factors, chaining, and decision trees builds deep analytical skills in symbolic logic.
3. Applying Systems to Real-World Problem Solving: Studying MYCIN and DENDRAL demonstrates how AI assists professionals in high-stakes fields like medicine and chemistry.
4. Understanding Limitations & Evolution Toward Hybrid AI: Provides historical context for the transition from expert rules to neuro-symbolic systems.
5. Preparing for Advanced Careers: Supports university study in AI, knowledge engineering, decision support systems, and explainable software development.
Frequently Asked Questions
1) What is an expert system and when should I use one?
An expert system encodes domain knowledge as explicit rules and reasons over a knowledge base to produce decisions with explanations. Use one when your domain requires auditability, stable policies, safety/compliance guardrails, or when stakeholders must see exactly why a conclusion was reached.
2) How do expert systems differ from machine learning models?
Rules come from subject matter experts, guidelines, and policy; ML learns patterns from data. Rules are transparent by construction; ML often needs post-hoc explanation. Combining them (neuro-symbolic) allows ML to extract evidence while rules enforce policy.
3) What is forward- vs. backward-chaining?
Forward-chaining starts from known facts and fires rules to derive new facts (great for real-time monitoring). Backward-chaining starts from a target goal and works backward to prove required premises (great for diagnostic Q&A).
4) How should I represent uncertainty (CFs, Bayesian, Dempster–Shafer, fuzzy)?
Certainty factors are pragmatic and simple (-1 to +1). Bayesian updating provides principled probabilities when priors are known. Dempster-Shafer models explicit ignorance. Fuzzy logic handles continuous linguistic gradations.
5) How do I resolve conflicting rules?
Define a conflict set policy using rule salience (priority), specificity (more conditions beat fewer), and recency (newer facts first). Enforce refraction to prevent duplicate firings.
6) What’s the right way to acquire and maintain knowledge?
Interview SMEs using golden cases (typical, edge, and counter-examples). Write rules in IF-THEN-BECAUSE format. Version rules, schemas, and transforms, and review changes with automated test suites before deployment.
7) How do I integrate ML with an expert system?
Use ML-to-facts (run models first and pass outputs into Working Memory), rules-to-ML (use rules as execution gates), or co-decision adjudication (resolve disagreements using risk/confidence matrices).
8) How do I test and monitor an expert system?
Maintain golden test cases for regression testing. Ensure trace parity by logging fired rules and used evidence. Track latency percentiles, agenda size, and Working Memory size while monitoring data/calibration drift.
9) What are common performance bottlenecks and quick fixes?
Enable refraction to stop agenda explosions. Index high-cardinality slots to speed up RETE joins. Add TTL expirations to prevent Working Memory bloat, and move external I/O operations outside the rule evaluation loop.
10) When should I not use an expert system?
Avoid using pure expert systems for high-dimensional perception tasks (vision, raw speech recognition), rapidly shifting un-codified patterns, or high-frequency continuous control problems without stable rule structures.
End-of-Page Exercises & Assessment
Part 1: Review Questions
Q1: What are expert systems and how do they function in the realm of artificial intelligence?
Answer: Expert systems are AI programs that mimic human expert decision-making using a knowledge base and inference engine. They apply explicit logical rules to input data to simulate reasoning and generate explainable conclusions in domains like medicine, finance, and engineering.
Q2: What are the primary components of an expert system, and how do they work together?
Answer: 1. Knowledge Base (stores domain facts/rules), 2. Inference Engine (applies forward/backward chaining logic), 3. User Interface (handles input/output), and 4. Explanation Facility (shows rule derivation traces).
Q3: How do expert systems simulate human decision-making processes?
Answer: They encode domain knowledge into “IF-THEN” rules. An inference engine evaluates these rules iteratively against working memory facts, deriving intermediate sub-goals until a final conclusion is established.
Q4: What role does a knowledge base play in an expert system?
Answer: It serves as the central repository containing facts, heuristics, and domain rules. The depth and accuracy of the knowledge base directly govern the quality and reliability of the expert system’s decisions.
Q5: How does the inference engine process data to arrive at a conclusion?
Answer: It matches active facts in Working Memory against rule conditions in Production Memory, resolves rule conflicts on an agenda (via salience, specificity, recency), and fires selected rules to assert new facts.
Q6: What are some common applications of expert systems in the IT and AI sectors?
Answer: Medical diagnosis (MYCIN), financial credit scoring (FICO), computer hardware configuration (XCON), legal compliance auditing, precision agriculture, and industrial predictive maintenance.
Q7: How do rule-based reasoning and knowledge representation contribute to effectiveness?
Answer: They structure complex domain know-how into modular, human-readable, and auditable formats, enabling precise control over edge cases and policy exceptions.
Q8: What challenges do developers face when building and maintaining expert systems?
Answer: The “knowledge acquisition bottleneck” (eliciting tacit knowledge from SMEs), managing rule contradictions/cycles as knowledge bases scale, and manually updating rules when domain policies change.
Q9: How has the evolution of AI impacted the development and performance of expert systems?
Answer: Modern AI connects expert rule engines with neural networks in neuro-symbolic designs: ML handles raw perception (NLP, vision), while rule engines enforce deterministic safety guardrails and business logic.
Q10: What future developments are anticipated in expert system technology?
Answer: Integration with automated rule learning (mining candidate rules from data), real-time streaming RETE execution on edge IoT devices, and LLM-assisted knowledge base authoring with SME verification.
Part 2: Thought-Provoking Questions
Q1: How might expert systems revolutionize decision-making in high-stakes industries like healthcare and finance?
Analysis: By eliminating human fatigue, bias, and variance. In healthcare, expert systems evaluate clinical guidelines against patient vitals 24/7 to flag early sepsis. In finance, they enforce instant, auditable compliance checks across millions of daily transactions while explaining adverse credit decisions automatically.
Q2: What ethical considerations should be addressed when deploying expert systems in sensitive areas?
Analysis: Key issues include rule bias (encoding flawed SME assumptions), transparency (ensuring non-technical users understand explanations), accountability (who is liable when an expert system advice fails?), and data privacy during fact ingestion.
Q3: How can the integration of expert systems with other AI technologies enhance their capabilities?
Analysis: Pure rule systems struggle with raw pixels or unstructured text. Coupling rules with deep learning allows computer vision models to detect visual defects or medical images, passing structured confidence facts into rule engines for safety adjudication.
Q4: What challenges might arise in scaling expert systems for enterprise-level applications?
Analysis: Exponential pattern matching costs (agenda explosions, wide RETE joins) and rule management bloat. Solutions include modular rule grouping, Working Memory scoping per case, and isolated microservice deployments.
Q5: How might expert systems evolve to better handle uncertainty and incomplete information?
Analysis: By transitioning from binary logic to hybrid uncertainty engines that combine Certainty Factors, Bayesian network priors, and Fuzzy Logic membership functions within the same RETE pattern matching loop.
Q6: What potential impact could expert systems have on workforce productivity in large organizations?
Analysis: Automating repetitive decision workflows frees senior human experts to focus on complex edge cases, strategy, and R&D while standardizing operational decision quality across junior staff.
Q7: How might advancements in natural language processing (NLP) enhance usability?
Analysis: NLP allows users to query knowledge bases using conversational speech or text, while generative models can synthesize formal rule derivation traces into natural executive summaries.
Q8: What strategies can be employed to improve knowledge base maintainability?
Analysis: Modularizing rule sets by domain, enforcing strict canonical fact schemas, using decision tables for policy matrices, and running automated regression test suites against “golden cases.”
Q9: How might expert systems be adapted to provide real-time decision support in dynamic environments?
Analysis: By implementing incremental stream reasoning (delta facts), capping agenda activation counts, and deploying lightweight RETE engines directly onto edge devices or cloud event buses.
Q10: How could interdisciplinary research contribute to the next generation of expert systems?
Analysis: Combining cognitive psychology (human reasoning models), legal studies (formal compliance logic), and computer science (neuro-symbolic neural network integration) creates highly intuitive, verifiable AI interfaces.
Q11: What potential does the integration of expert systems with IoT technologies have for industrial automation?
Analysis: Sensor networks stream real-time telemetry into rule engines that detect anomalous vibration patterns, automatically triggering preventive maintenance or line shutdowns before hardware failure occurs.
Q12: How might future trends in AI impact the evolution of expert systems?
Analysis: The convergence of LLMs, vector search, and symbolic rules will allow LLMs to propose candidate rules from unstructured documents, which SMEs audit and publish to deterministic rule engines.
Part 3: Numerical Engineering Problems
Problem 1: Rule Evaluation Latency & Daily Compute Workload
Question: An expert system evaluates 250 rules per query. Each rule evaluation takes 0.004 seconds. If the system processes 5,000 queries per day, calculate:
1. Processing time per query.
2. Total daily rule evaluation execution time in seconds.
Step-by-step Solution:
1. Time per query = 250 rules × 0.004 s = 1.0 second.
2. Total daily execution time = 5,000 queries × 1.0 s = 5,000 seconds (approx. 1.39 hours).
Final Answer: Average time per query is 1 second; total daily evaluation time is 5,000 seconds.
Problem 2: Compound Monthly Growth of Knowledge Base Rules
Question: An expert system’s knowledge base grows at a compound rate of 4% per month. If it starts with 1,200 rules, calculate the total number of rules after 12 months.
Step-by-step Solution:
1. Apply compound growth formula: N = 1,200 × (1 + 0.04)12.
2. Calculate factor: (1.04)12 ≈ 1.60103.
3. Compute final rule count: 1,200 × 1.60103 = 1,921.24 ≈ 1,921 rules.
Final Answer: The knowledge base contains approximately 1,921 rules after 12 months.
Problem 3: Daily Rule Evaluation Workload from Active Subsets
Question: An inference engine examines 15% of a 500-rule knowledge base per query. If the system processes 2,000 queries per day, calculate the total number of rule evaluations performed.
Step-by-step Solution:
1. Rules evaluated per query = 0.15 × 500 = 75 rules.
2. Total daily evaluations = 75 rules/query × 2,000 queries = 150,000 rule evaluations.
Final Answer: The system performs 150,000 rule evaluations per day.
Problem 4: Diagnostic Accuracy & Error Rate Calculation
Question: A diagnostic expert system achieves 92% accuracy on a test set of 800 cases. Calculate:
1. Number of correct diagnoses.
2. Number of errors.
3. Error rate percentage.
Step-by-step Solution:
1. Correct diagnoses = 800 × 0.92 = 736 cases.
2. Errors = 800 – 736 = 64 cases.
3. Error rate percentage = (64 / 800) × 100 = 8%.
Final Answer: 736 correct diagnoses, 64 errors, and an 8% error rate.
Problem 5: Rule Engineering Development Cost per Query
Question: An expert system costs $600 per rule to author and validate. If the knowledge base contains 450 rules and handles 90,000 queries over its operational lifetime, calculate:
1. Total development cost.
2. Development cost amortized per query.
Step-by-step Solution:
1. Total cost = 450 rules × $600 = $270,000.
2. Cost per query = $270,000 / 90,000 queries = $3.00 per query.
Final Answer: Total development cost is $270,000 ($3.00 per query).
Problem 6: Quarterly Rule Base Addition Growth
Question: A rule-based system expands its knowledge base by adding 100 rules every 3 months. If it starts with 500 rules, calculate total rules after 1 year and the overall percentage increase.
Step-by-step Solution:
1. Updates per year = 12 / 3 = 4 updates. Total new rules = 4 × 100 = 400 rules.
2. Total rules after 1 year = 500 + 400 = 900 rules.
3. Percentage increase = ((900 – 500) / 500) × 100 = 80% increase.
Final Answer: Total rules equal 900, representing an 80% increase.
Problem 7: Batch Query Execution Time
Question: An inference engine processes rules at 0.003 seconds per rule. If an average query evaluates 120 rules, calculate processing time per query and total time required for 5,000 queries.
Step-by-step Solution:
1. Time per query = 120 rules × 0.003 s = 0.36 seconds.
2. Total time for 5,000 queries = 5,000 × 0.36 s = 1,800 seconds (30 minutes).
Final Answer: Processing time is 0.36 seconds per query and 1,800 seconds total.
Problem 8: Confidence Increment Iteration Threshold
Question: A diagnostic system requires a rule confidence threshold of 0.80 before taking action. If confidence increases by 0.04 with each successful inference pass starting from 0.60, calculate the number of inferences required.
Step-by-step Solution:
1. Required confidence gain = 0.80 – 0.60 = 0.20.
2. Number of inferences = 0.20 / 0.04 = 5 inferences.
Final Answer: 5 successful inferences are required to reach the 0.80 threshold.
Problem 9: Engine Efficiency & Correct Rule Evaluations
Question: A rule matching engine operates at 95% efficiency. It processes 1,000 queries, each evaluating 200 rules. Calculate total rule evaluations and effective correct evaluations.
Step-by-step Solution:
1. Total evaluations = 1,000 × 200 = 200,000 evaluations.
2. Effective correct evaluations = 200,000 × 0.95 = 190,000 evaluations.
Final Answer: 200,000 total evaluations with 190,000 effective correct evaluations.
Problem 10: Daily Processing Hours & Response Latency
Question: An expert system’s average response time is 0.25 seconds per query. If the system processes 12,000 queries per day, calculate total processing time in hours and average response time in milliseconds.
Step-by-step Solution:
1. Total processing time = 12,000 × 0.25 s = 3,000 seconds.
2. Convert to hours = 3,000 / 3,600 ≈ 0.833 hours.
3. Response latency in ms = 0.25 s × 1,000 = 250 ms.
Final Answer: Total daily execution time is 0.833 hours with an average latency of 250 ms.
Problem 11: Quarterly Compound Growth of Knowledge Base
Question: A knowledge base expands by 10% each quarter. If the system starts with 800 rules, calculate total rules after 1 year (4 quarters) using compound growth.
Step-by-step Solution:
1. Growth factor per quarter = 1 + 0.10 = 1.10.
2. Total rules = 800 × (1.10)4 = 800 × 1.4641 = 1,171.28 ≈ 1,171 rules.
Final Answer: The rule count reaches approximately 1,171 rules after 1 year.
Problem 12: Accuracy Lift & Decision Improvement
Question: An expert system improves decision accuracy from 85% to 95% after rule optimization. Across a workload of 50,000 queries, calculate the increase in correct decisions and percentage improvement over the baseline.
Step-by-step Solution:
1. Initial correct decisions = 50,000 × 0.85 = 42,500.
2. Post-optimization correct decisions = 50,000 × 0.95 = 47,500.
3. Absolute increase = 47,500 – 42,500 = 5,000 additional correct decisions.
4. Relative improvement = (5,000 / 42,500) × 100 ≈ 11.76%.
Final Answer: 5,000 additional correct decisions, representing an 11.76% improvement.
Expert Systems: Conclusion & Next Steps
AI Sub-Cluster Links & Academic References
-
MLOps & AI Infrastructure
Explore automated CI/CD/CT training pipelines, containerized model serving, and feature stores. -
AI Safety, Ethics & Governance
Master fairness auditing, disparate impact evaluation, safety guardrails, and compliance standards. -
Edge AI & Embedded Machine Learning
Learn TinyML techniques, model quantization, and optimization strategies for resource-constrained microcontrollers. -
Artificial Intelligence Overview Hub
Return to the primary AI hub covering machine learning paradigms, deep learning, and intelligent systems.
External References
- MYCIN: Computer-Based Medical Consultations (Shortliffe, 1976) – Seminal research introducing certainty factors.
- Rete: A Fast Algorithm for the Many Pattern/Many Object Pattern Match Problem (Forgy, 1982) – Foundational RETE algorithm paper.