
Standard model-free reinforcement learning algorithms—such as Deep Q-Networks (DQN) or Proximal Policy Optimization (PPO)—learn control policies through trial-and-error interaction with an environment. While highly effective, model-free methods require millions of physical interactions to learn complex tasks. In hardware domains like robotics and industrial control, collecting millions of real-world physical interactions causes severe mechanical wear, safety hazards, and unsustainable time costs. Model-Based Reinforcement Learning (MBRL) addresses this bottleneck by training a predictive World Model that approximates environmental dynamics, allowing agents to learn policies primarily within synthetic imagination.
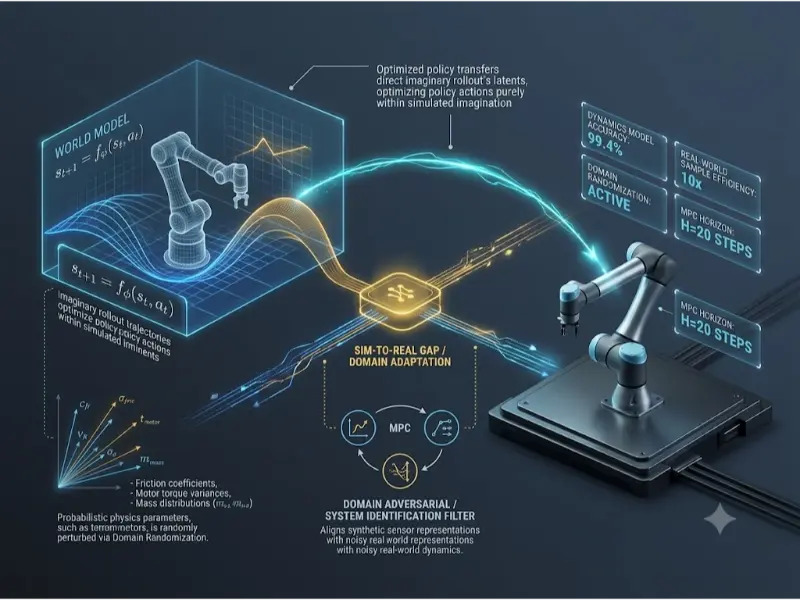
Complementing MBRL is the discipline of Sim-to-Real Transfer: training policies inside ultra-fast digital physics simulators (e.g., MuJoCo, Isaac Gym) and transferring them to physical hardware. However, transferring synthetic policies directly to physical hardware encounters the Reality Gap (Sim-to-Real Gap)—unmodeled friction, motor latency, sensor noise, and structural flex in real hardware. Overcoming this gap requires robust techniques such as Domain Randomization, System Identification, and Domain Adaptation.
Interactive Quick Review: Model-Free vs. Model-Based RL
What is the fundamental difference between Model-Free RL and Model-Based RL regarding environment dynamics?
Toggle Answer
Answer: Model-Free RL directly maps states to actions or values without estimating how the environment behaves. Model-Based RL explicitly learns or utilizes a transition model fφ(st+1 | st, at) to predict future states and rewards, enabling trajectory rollout planning and lookahead simulation without taking physical environment steps.
Architectural & Theoretical Deep Dives
1. World Model Formulation & Latent Dynamics
A predictive World Model learns a parameterized dynamics transition function fφ that models the next state st+1 and reward rt given current state st and action at:
$$\hat{s}_{t+1}, \hat{r}_t = f_\phi(s_t, a_t)$$
In high-dimensional visual domains (e.g., camera control), raw images are too noisy for pixel-level rollout predictions. Modern architectures like Dreamer (v1-v3) compress observations xt into a compact low-dimensional latent space zt using a Recurrent State-Space Model (RSSM) consisting of:
- Representation Model (Encoder): qθ(zt | zt-1, at-1, xt)
- Recurrent Transition Model (Prior): pφ(zt | zt-1, at-1)
- Reward Predictor: pψ(rt | zt)
2. Dyna Architecture & MBPO (Model-Based Policy Optimization)
The classical Dyna-Q algorithm combines real environment experience with simulated mental rollouts:
- Direct RL: Update policy/values using real environment transitions (s, a, r, s’).
- Model Learning: Fit transition model parameters φ using supervised loss on collected real transitions.
- Planning: Sample random imaginary states s and actions a, generate synthetic next states s’ = fφ(s, a), and update policy parameters within synthetic rollouts.
Model Exploitation / Model Bias: If simulated rollouts extend too far into the future, small prediction errors in fφ compound exponentially, causing policy optimization to exploit model inaccuracies. MBPO solves this compounding error by restricting imaginary rollouts to short horizons (e.g., k = 1 to 15 steps) starting from real historical state distributions.
3. Sim-to-Real Transfer & Domain Randomization (DR)
The simulator physics model relies on nominal parameters e ∼ P(E) (such as link masses, surface friction, motor damping, and sensor latency). Domain Randomization (DR) trains a policy across a wide probability distribution of physics dynamics rather than a single fixed simulator:
$$\max_\theta \mathbb{E}_{e \sim P(E)} \left[ \mathbb{E}_{\tau \sim \pi_\theta(e)} \left[ \sum_{t=0}^T \gamma^t r(s_t, a_t) \right] \right]$$
By exposing the neural policy πθ to extreme dynamic variability during simulated training, the real world appears simply as another un-sampled variation within the randomized training distribution.
4. Python Implementation: Model Predictive Control (MPC) Random Shooting Planner
import torch

import torch.nn as nn


class DynamicWorldModel(nn.Module):

    """Simple MLP World Model predicting delta_state from state and action."""

    def __init__(self, state_dim: int, action_dim: int):

        super().__init__()

        self.net = nn.Sequential(

            nn.Linear(state_dim + action_dim, 64),

            nn.ReLU(),

            nn.Linear(64, state_dim)

        )

    def forward(self, state: torch.Tensor, action: torch.Tensor) -> torch.Tensor:

        x = torch.cat([state, action], dim=-1)

        return state + self.net(x) # Predict next state via residual connection


def mpc_random_shooting(world_model: nn.Module, current_state: torch.Tensor,

                        horizon: int = 10, num_samples: int = 500, action_dim: int = 2) -> torch.Tensor:

    """

    MPC Random Shooting Planner: Samples N random action sequences,

    simulates trajectories through the world model, and selects the optimal initial action.

    """

    # Sample random action sequences: [num_samples, horizon, action_dim]

    candidate_actions = torch.distributions.Uniform(-1.0, 1.0).sample((num_samples, horizon, action_dim))

    states = current_state.repeat(num_samples, 1) # Expand current state

    returns = torch.zeros(num_samples)


    with torch.no_grad():

        for t in range(horizon):

            actions = candidate_actions[:, t, :]

            states = world_model(states, actions)

            # Synthetic reward objective: Minimize distance to origin (0,0)

            rewards = -torch.norm(states, dim=-1)

            returns += (0.99 ** t) * rewards


    best_trajectory_idx = torch.argmax(returns)

    best_first_action = candidate_actions[best_trajectory_idx, 0, :]

    return best_first_action


# Example Setup

state_dim, action_dim = 4, 2

model = DynamicWorldModel(state_dim, action_dim)

init_state = torch.tensor([1.5, -0.5, 0.2, 0.0])


optimal_action = mpc_random_shooting(model, init_state, horizon=10, num_samples=200, action_dim=action_dim)

print("MPC Selected Initial Action:", optimal_action.numpy())
Interactive Quick Review: Domain Randomization vs. System Identification
How does System Identification differ from Domain Randomization in bridging the Sim-to-Real gap?
Toggle Answer
Answer: System Identification seeks to measure and calibrate exact physical parameter constants (e.g., exact mass, friction, gear backlash) on hardware to make the simulator match reality as closely as possible. Domain Randomization accepts that simulator mismatch is inevitable and instead trains the policy across a randomized distribution of dynamic parameters so the learned policy becomes broadly robust to dynamic variations.
Taxonomy & Optimization Comparison Matrix
| MBRL / Transfer Paradigm | World Model Type | Planning Method | Sample Efficiency | Primary Challenge |
|---|---|---|---|---|
| MPC + World Model (PETS / Random Shooting) | Ensemble Physics Network | Online Lookahead Sampling | High (< 100k steps) | High computational latency during real-time control loops |
| Dyna / MBPO (Model-Based Policy Opt.) | Short-Horizon Dynamic Ensemble | Model-Augmented Policy Gradient | Very High | Susceptible to model exploitation on long synthetic rollouts |
| Dreamer (v1-v3 / RSSM) | Recurrent Latent Space (RSSM) | Latent Imagination Backprop | Ultra High (Visual domains) | Complex hyperparameter tuning for latent representation loss |
| Domain Randomization (Sim-to-Real) | GPU Physics Engine (Isaac/MuJoCo) | Model-Free RL across randomized simulator | Low in sim, Ultra High in Real | Conservative “over-robust” policies if randomization range is too wide |
Applications, Trade-offs, & Future Outlook
Real-World Applications
- Quadrupedal & Humanoid Robotics (Anymal, Unitree): Training locomotion policies in physics simulators with randomized friction, slope inclinations, and payload weights, then zero-shot deploying onto physical hardware.
- Autonomous Industrial Assembly: High-precision robotic insertion and peg-in-hole manipulation using tactile feedback policies conditioned on compliance dynamic models.
- Chemical Plant & Energy Grid Control: Optimizing multi-stage distillation columns and HVAC power distribution by querying predictive thermal world models without disrupting physical plant safety.
Engineering Trade-offs
The core trade-off in MBRL is Sample Efficiency vs. Computational Complexity. Model-based methods require orders of magnitude fewer physical steps than model-free algorithms. However, learning a high-capacity neural world model requires substantial compute GPU overhead during training. Furthermore, if the world model is inaccurate, online Model Predictive Control (MPC) can select catastrophic trajectories that exploit simulator flaws.
Future Outlook & Emerging Research
Research is rapidly expanding into Generative Video World Models (such as Sora-style diffusion architectures acting as simulator backends) and Real-Time Adaptive System Identification. Future robotic systems will infer physical property changes (e.g., a robot arm gripping an unexpectedly heavy box) within milliseconds using recurrent context latent variables, adapting policy execution online without retraining.
Frequently Asked Questions
What is Model Bias (Model Exploitation) in MBRL?
Model Bias occurs when an RL policy learns to take advantage of inaccuracies, bugs, or unphysical shortcuts in the learned world model to achieve high synthetic rewards that fail completely when deployed in the actual physical environment.
What is the Difference between Online Planning and Policy Learning in MBRL?
Online Planning (e.g., MPC) uses the world model at inference time to evaluate candidate action sequences forward in time without storing a explicit neural policy. Policy Learning (e.g., Dreamer, MBPO) uses the world model offline to train an actor-critic neural network policy that acts instantaneously at runtime.
What is Zero-Shot Sim-to-Real Transfer?
Zero-Shot transfer means deploying a control policy trained exclusively inside a virtual simulator directly onto physical hardware without performing any additional fine-tuning or training steps in the physical world.
How does an Ensemble of World Models prevent catastrophic policy failure?
By training multiple independent world models (an ensemble) on the same experience data, the variance across model predictions serves as an epistemic uncertainty metric. The policy is penalized when entering state-action regions where ensemble model predictions diverge.
End-of-Page Exercises & Assessment
Part 1: Review Questions
Q1: Define the transition dynamics function of a World Model.
Answer: A World Model transition dynamics function fφ(st, at) is a predictive function that estimates the next environment state st+1 (or state change Δs) and immediate reward rt given current state st and action at.
Q2: What is the primary purpose of a Recurrent State-Space Model (RSSM) in Dreamer?
Answer: An RSSM separates deterministic memory states (RNN/GRU) from stochastic latent variables, enabling long-horizon memory retention while maintaining probabilistic representation of state uncertainties in vision-based environments.
Q3: Explain the term “Reality Gap” in robotic policy deployment.
Answer: The Reality Gap (or Sim-to-Real gap) refers to the performance degradation observed when a policy trained in a synthetic simulator fails on physical hardware due to unmodeled physical phenomena like latency, friction, and sensor noise.
Q4: How does Model Predictive Control (MPC) execute actions in real time?
Answer: At state st, MPC plans an optimal action sequence over horizon H using the world model, executes only the very first action at in the real environment, observes new state st+1, and replans over horizon H at the next timestep (receding horizon control).
Q5: What is Automatic Domain Randomization (ADR)?
Answer: ADR is an advanced Sim-to-Real technique that automatically expands the randomization boundaries of physical simulation parameters whenever the policy achieves high performance thresholds on current parameter distributions.
Part 2: Thought-Provoking Questions
Q1: Over-Conservatism in Extreme Domain Randomization
Scenario: An engineering team randomizes simulator mass by ±300% and friction by ±500% to ensure quadrupedal robot stability. Upon deployment, the robot moves excessively slow and refuses to jump across small gaps.
Analysis: When Domain Randomization ranges are set excessively wide, the policy learns an overly conservative “worst-case scenario” strategy (minimax survival behavior) that sacrifces performance for safety. Mitigating over-conservatism requires narrowing randomization bounds to realistic dynamic ranges, utilizing System Identification to ground bounds, or employing Adaptive Context-Conditioned Policies (passing latent dynamics embeddings to the policy at runtime).
Q2: Epistemic Uncertainty and Out-of-Distribution Rollouts
Scenario: A Model-Based agent plans an imaginary trajectory 20 steps into the future, predicting a reward of +1000. When executed on real hardware, the robot crashes within 3 steps.
Analysis: The planner suffered from unconstrained model rollouts in state spaces where the world model had low training data density. The optimizer exploited delusional state predictions where the ungrounded model output false high rewards. To fix this, the agent must implement Ensemble Model Variance Penalties—subtracting scalar reward points proportional to the prediction variance across an ensemble of world models—to keep imaginary rollouts anchored within familiar state distributions.
Part 3: Numerical Engineering Problems
Problem 1: Compounding Prediction Error on Imaginary Trajectories
Question: A learned World Model has a constant per-step mean absolute state transition error ε = 0.05.
1. Assuming state error compounds additively per step t, express the expected state error E(t) at step t = 10.
2. In a worst-case multiplicative error scenario where error scales as E(t) = ε · (1.2)t-1, calculate the cumulative trajectory error accumulated over a 10-step imagination rollout (from t = 1 to t = 10).
Step-by-step Solution:
1. Calculate additive error at step t = 10:
Eadd(10) = 10 × ε = 10 × 0.05 = 0.50
2. Calculate worst-case multiplicative cumulative error: $$\text{Total Error} = \sum_{t=1}^{10} 0.05 \times (1.2)^{t-1} = 0.05 \times \sum_{k=0}^{9} (1.2)^k$$
Using geometric series sum formula $S_n = \frac{a(r^n – 1)}{r – 1}$: $$S_{10} = \frac{0.05 \times ((1.2)^{10} – 1)}{1.2 – 1} = \frac{0.05 \times (6.19173 – 1)}{0.2} = \frac{0.05 \times 5.19173}{0.2} = \frac{0.259586}{0.2} \approx 1.2979$$
Final Answer: Additive step-10 state error is 0.50; cumulative multiplicative error across 10 steps is 1.2979.
Problem 2: MPC Trajectory Evaluation & Optimal Action Selection
Question: An MPC Random Shooting planner evaluates 3 candidate initial actions (a1, a2, a3) over a horizon H = 3 steps with discount factor γ = 0.90. The world model predicts the following step reward sequences:
• Action a1: r1 = 2.0, r2 = 3.0, r3 = 4.0
• Action a2: r1 = 5.0, r2 = 1.0, r3 = 1.0
• Action a3: r1 = 1.0, r2 = 4.0, r3 = 5.0
Calculate the discounted return G for each trajectory and identify the optimal action selected by MPC.
Step-by-step Solution:
1. Calculate discounted return G1 for Action a1: $$G_1 = 2.0 + (0.90 \times 3.0) + (0.90^2 \times 4.0) = 2.0 + 2.70 + (0.81 \times 4.0) = 2.0 + 2.70 + 3.24 = 7.94$$
2. Calculate discounted return G2 for Action a2: $$G_2 = 5.0 + (0.90 \times 1.0) + (0.90^2 \times 1.0) = 5.0 + 0.90 + 0.81 = 6.71$$
3. Calculate discounted return G3 for Action a3: $$G_3 = 1.0 + (0.90 \times 4.0) + (0.90^2 \times 5.0) = 1.0 + 3.60 + (0.81 \times 5.0) = 1.0 + 3.60 + 4.05 = 8.65$$
Final Answer: Returns are G1 = 7.94, G2 = 6.71, and G3 = 8.65. The MPC planner selects action a3 with the highest discounted return of 8.65.
Reinforcement Learning Sub-Cluster
-
RLHF & AI Alignment
Explore PPO, DPO, reward modeling, and aligning foundation models with human utility and intent. -
Multi-Agent Reinforcement Learning (MARL)
Master Markov games, Centralized Training with Decentralized Execution (CTDE), and Nash Equilibrium coordination. -
Reinforcement Learning Hub
Return to the main Reinforcement Learning overview covering MDPs, Q-Learning, Policy Gradients, and Actor-Critic methods.
External Academic & Technical References
- Dream to Control: Learning Behaviors by Latent Imagination (Hafner et al., Dreamer / ICLR 2020) – Foundational paper on latent world models learning policies in imagination.
- When to Trust Your Model: Model-Based Policy Optimization (Janner et al., MBPO / NeurIPS 2019) – Key paper demonstrating sample-efficient policy learning via short-horizon synthetic rollouts.
- Domain Randomization for Transferring Deep Neural Networks from Simulation to the Real World (Tobin et al., IROS 2017) – Seminal paper establishing domain randomization for zero-shot sim-to-real robotic transfer.