
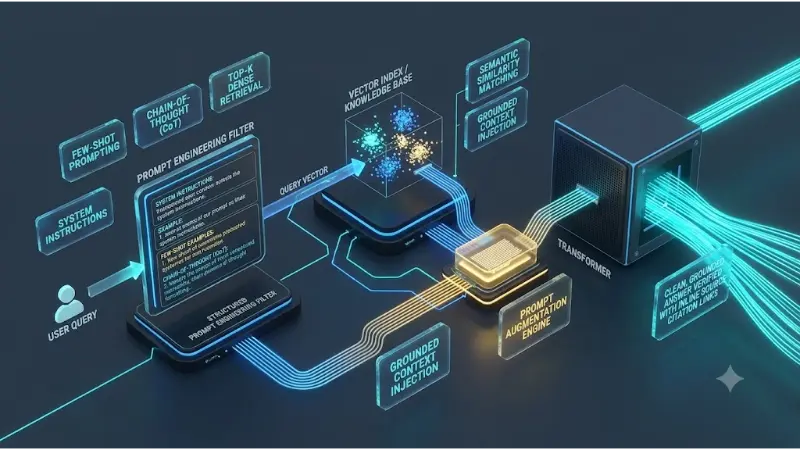
Interactive Quick Review: Fine-Tuning vs. RAG Grounding
Why is Retrieval-Augmented Generation (RAG) generally preferred over model fine-tuning for dynamic enterprise knowledge bases?
Toggle Answer
Answer: Fine-tuning bakes knowledge static into model weights, which is expensive, prone to catastrophic forgetting, and requires full retraining when document sets change. RAG keeps the LLM parametric weights fixed while injecting live, up-to-date document chunks directly into the prompt context window, guaranteeing source traceability and instant knowledge updates without compute overhead.
Architectural & Theoretical Deep Dives
1. In-Context Learning & Advanced Prompt Engineering Paradigms
In-Context Learning (ICL) leverages an LLM’s ability to condition its output on patterns supplied in the input prompt without updating network parameters θ. Key prompt engineering frameworks include:
- Zero-Shot & Few-Shot Prompting: Providing explicit input-output pairs inside the prompt to establish task structure and output schema formatting.
- Chain-of-Thought (CoT): Prompting the model to generate intermediate reasoning steps (“Let’s think step by step”) before producing a final answer, dramatically improving logical and arithmetic performance.
- ReAct (Reasoning + Acting): Combining CoT reasoning with action execution loops, allowing the LLM to dynamically determine when to call external APIs or retrieve missing information.
2. The Retrieval-Augmented Generation (RAG) Pipeline
A standard RAG pipeline operates across three distinct phases:
Phase A: Ingestion & Chunking: Raw documents are parsed, split into semantic text chunks ci (e.g., 512 tokens with 10% overlap), and passed through an embedding model E(·) to generate dense vector representations:
$$\mathbf{v}_i = E(c_i) \in \mathbb{R}^d$$
Phase B: Vector Retrieval: Given a user query q, the system computes query embedding $\mathbf{v}_q = E(q)$ and retrieves the top-K nearest neighbor chunks using cosine similarity or inner product search over a vector database index:
$$\text{Similarity}(q, c_i) = \frac{\mathbf{v}_q \cdot \mathbf{v}_i}{\|\mathbf{v}_q\| \|\mathbf{v}_i\|}$$
Phase C: Augmentation & Generation: The top-K retrieved text chunks are formatted into a system prompt wrapper as context C = {c1, c2, &dots;, cK}. The LLM generates response y conditioned on the augmented context:
$$P(y \mid q, C) = \prod_{t=1}^T P(y_t \mid y_{
Naive RAG suffers from retrieval precision loss when dense embeddings fail to capture keyword matches. Modern enterprise pipelines implement Advanced RAG Architectures:3. Advanced RAG Techniques: Re-Ranking and Naive RAG Mitigation
4. Python Implementation: Modular RAG Pipeline with Cosine Similarity
import torch

import torch.nn.functional as F

from typing import List, Dict


class SimpleVectorRAG:

    """

    Minimalist RAG pipeline illustrating vector storage, retrieval, and prompt augmentation.

    """

    def __init__(self, embedding_dim: int = 64):

        self.embedding_dim = embedding_dim

        self.document_chunks: List[str] = []

        self.vectors: torch.Tensor = torch.empty((0, embedding_dim))


    def _mock_embedding_model(self, text: str) -> torch.Tensor:

        """Simulates dense vector embedding generation."""

        torch.manual_seed(hash(text) % 100000)

        return F.normalize(torch.randn(1, self.embedding_dim), p=2, dim=-1)


    def add_documents(self, docs: List[str]):

        """Ingests and indexes document chunks into vector space."""

        for doc in docs:

            self.document_chunks.append(doc)

            emb = self._mock_embedding_model(doc)

            self.vectors = torch.cat([self.vectors, emb], dim=0)


    def retrieve(self, query: str, top_k: int = 2) -> List[Dict]:

        """Computes cosine similarity search over vector index."""

        query_emb = self._mock_embedding_model(query) # [1, dim]

        similarities = torch.mm(self.vectors, query_emb.T).squeeze(-1) # Cosine similarity

        top_scores, top_indices = torch.topk(similarities, k=top_k)


        results = []

        for score, idx in zip(top_scores, top_indices):

            results.append({"chunk": self.document_chunks[idx], "score": score.item()})

        return results


    def construct_augmented_prompt(self, query: str, top_k: int = 2) -> str:

        """Injects retrieved context into system prompt template."""

        retrieved_data = self.retrieve(query, top_k=top_k)

        context_str = "\n".join([f"- {item['chunk']}" for item in retrieved_data])


        prompt_template = (

            f"SYSTEM: Answer the user query strictly using the provided context chunks.\n"

            f"CONTEXT:\n{context_str}\n\n"

            f"USER QUERY: {query}\n"

            f"ANSWER:"

        )

        return prompt_template


# Example Execution

kb_docs = [

    "Transformer architectures utilize multi-head self-attention mechanisms.",

    "RAG systems mitigate LLM hallucinations by retrieving external vector context.",

    "Fine-tuning updates model weights while prompt engineering modifies input context."

]


rag_system = SimpleVectorRAG(embedding_dim=64)

rag_system.add_documents(kb_docs)

final_prompt = rag_system.construct_augmented_prompt("How does RAG stop hallucinations?")

print(final_prompt)
Interactive Quick Review: Cross-Encoder vs. Bi-Encoder Retrieval
Why do production RAG systems use Bi-Encoders for initial candidate retrieval and Cross-Encoders for re-ranking?
Toggle Answer
Answer: Bi-Encoders encode queries and documents independently into fixed vectors offline, allowing ultra-fast Approximate Nearest Neighbor (ANN) search over millions of items in milliseconds. Cross-Encoders process query and document concatenated together through full self-attention, capturing deeper semantic interaction but at high compute cost. Using Bi-Encoders to narrow millions to 50, followed by Cross-Encoders to pick top 5, balances speed with accuracy.
Taxonomy & Optimization Comparison Matrix
| Grounded AI Paradigm | Implementation Mechanism | Knowledge Latency | Context Footprint | Primary Failure Mode |
|---|---|---|---|---|
| Prompt Engineering (CoT / Few-Shot) | In-Context Instructions & Examples | Static (Injected manually) | High (Consumes input tokens) | Instruction drift or context window exhaustion |
| Naive RAG | Vector Similarity Top-K Chunk Injection | Real-Time (Database updates) | Moderate (Top-K chunks) | Irrelevant chunk retrieval / semantic vector mismatch |
| Advanced RAG (Hybrid + Re-Ranking) | Dense/Sparse Fusion + Cross-Encoder | Real-Time | Optimized (Highly targeted) | Increased retrieval latency overhead |
| Supervised Fine-Tuning (SFT) | Weight Gradient Updates (Δθ) | Slow (Requires retraining) | Zero (Baked into weights) | Knowledge hallucination / catastrophic forgetting |
Applications, Trade-offs, & Future Outlook
Real-World Applications
- Legal & Regulatory Compliance Search: Parsing complex, evolving statutory codes and internal contracts to generate citations grounded in exact line-numbered sources.
- Enterprise Customer Support Support: Grounding automated support agents on live technical manuals, product release notes, and ticketing systems.
- Clinical Medical Decision Support: Assisting healthcare professionals by querying recent medical research literature and clinical guidelines.
Engineering Trade-offs
The core challenge in RAG deployment is the Retrieval Precision vs. Context Window Window Cost Trade-off. Injecting dozens of retrieved chunks increases recall (reducing missing facts) but rapidly inflates per-query API token costs, slows processing latency, and risks triggering “Lost in the Middle” attention distraction where the LLM ignores relevant information buried inside dense prompts.
Future Outlook & Emerging Research
Research is rapidly evolving toward GraphRAG (constructing Knowledge Graphs from document collections to enable multi-hop reasoning across interconnected entities) and Agentic RAG, where autonomous agents dynamically decide when to retrieve, reformulate queries, or trigger secondary database searches based on intermediate generation confidence.
Frequently Asked Questions
What is the “Lost in the Middle” Phenomenon in Long-Context Prompts?
Research demonstrates that LLMs attend strongly to information placed at the very beginning or very end of long input prompts, but frequently fail to retrieve or reason over facts placed in the middle of a large context block. Advanced RAG systems mitigate this by re-ordering retrieved chunks so the most relevant facts reside near the prompt boundaries.
How does Chunk Size affect RAG performance?
Small chunks (e.g., 128 tokens) provide precise vector search matches but may lack required surrounding context. Large chunks (e.g., 1024 tokens) preserve context but can dilute vector similarity embeddings with irrelevant text. Optimal systems use parent-child chunking (searching small child vectors but injecting larger parent context blocks into the LLM prompt).
What is Reciprocal Rank Fusion (RRF)?
RRF is an algorithm used in Hybrid Search to combine rank positions from different retrieval systems (e.g., sparse keyword BM25 and dense vector cosine similarity) into a unified scoring list without needing score normalization.
What is Hypothetical Document Embeddings (HyDE)?
HyDE is a query transformation technique where the LLM generates a hypothetical answer to a user query first. The system then embeds this generated hypothetical document and uses its vector to search the database, often matching real document vectors better than the raw short query.
End-of-Page Exercises & Assessment
Part 1: Review Questions
Q1: Define the core operational difference between In-Context Learning and Parameter Fine-Tuning.
Answer: In-Context Learning conditions LLM outputs by feeding instructions and examples directly into the input context window while keeping neural network weights θ completely frozen. Parameter Fine-Tuning uses backpropagation to update internal network weights θ using supervised gradient updates.
Q2: State the primary objective of Chain-of-Thought (CoT) prompting.
Answer: CoT prompting encourages the model to generate a sequence of explicit intermediate reasoning steps prior to giving the final answer, decomposing complex multi-step problems and significantly improving logical accuracy.
Q3: What role does an Embedding Model play in a RAG ingestion pipeline?
Answer: An embedding model converts unstructured text chunks into high-dimensional numerical dense vectors that capture semantic meaning, enabling mathematical similarity comparison in vector space.
Q4: Explain the purpose of a Cross-Encoder Re-Ranker in Advanced RAG.
Answer: A Cross-Encoder evaluates deep joint self-attention between the query and candidate document chunks simultaneously, providing highly accurate relevance re-scoring to select the highest-quality chunks before prompt construction.
Q5: How does Parent-Child Chunking resolve context granularity conflicts?
Answer: Parent-Child chunking indexes small text segments (children) for high-precision vector search, but retrieves and injects their larger surrounding text blocks (parents) into the prompt to provide full contextual background to the LLM.
Part 2: Thought-Provoking Questions
Q1: Mitigating Vector Search Failure on Acronyms and Technical Codes
Scenario: An internal enterprise RAG system fails when users search for specific error codes like “ERR_SYS_8091”. The vector database retrieves general error handling documents instead of the exact troubleshooting manual for code 8091.
Analysis: Dense embedding models abstract text into semantic concept space, often failing to capture exact keyword or alphanumeric string matches. The engineering solution is to implement Hybrid Search—combining sparse keyword search (BM25 or full-text inverted index) with dense vector search, fused via Reciprocal Rank Fusion (RRF), ensuring exact string identifiers receive high rank scores.
Q2: Overcoming Hallucinations in Multi-Hop Document Reasoning
Scenario: A user asks, “What was the revenue growth rate of the company whose CEO visited Tokyo in Q3?” A standard RAG system fails because no single document chunk contains both the CEO’s travel log and the financial revenue figures.
Analysis: Single-step top-K retrieval fails on multi-hop questions requiring relational synthesis across distinct documents. The issue can be resolved using GraphRAG (linking entities via knowledge graph triplets) or an Agentic RAG loop, where the model breaks the prompt into sub-queries: first retrieving the travel log to identify the company name, then executing a second retrieval step for that company’s financial growth metrics.
Part 3: Numerical Engineering Problems
Problem 1: Cosine Similarity Vector Retrieval Calculation
Question: Given a user query vector $\mathbf{v}_q = [0.6, 0.8]$ and two document chunk vectors $\mathbf{v}_1 = [0.8, 0.6]$ and $\mathbf{v}_2 = [0.0, 1.0]$:
1. Compute the Cosine Similarity score between the query vector $\mathbf{v}_q$ and chunk vector $\mathbf{v}_1$.
2. Compute the Cosine Similarity score between the query vector $\mathbf{v}_q$ and chunk vector $\mathbf{v}_2$.
3. Determine which chunk a RAG system will select as Top-1 candidate.
Step-by-step Solution:
1. Cosine Similarity for Chunk 1:
• Vector Magnitudes: $\|\mathbf{v}_q\| = \sqrt{0.6^2 + 0.8^2} = \sqrt{0.36 + 0.64} = 1.0$; $\|\mathbf{v}_1\| = \sqrt{0.8^2 + 0.6^2} = 1.0$.
• Dot Product: $\mathbf{v}_q \cdot \mathbf{v}_1 = (0.6 \times 0.8) + (0.8 \times 0.6) = 0.48 + 0.48 = 0.96$.
• Cosine Similarity 1 = $0.96 / (1.0 \times 1.0) = \mathbf{0.96}$.
2. Cosine Similarity for Chunk 2:
• Vector Magnitude: $\|\mathbf{v}_2\| = \sqrt{0.0^2 + 1.0^2} = 1.0$.
• Dot Product: $\mathbf{v}_q \cdot \mathbf{v}_2 = (0.6 \times 0.0) + (0.8 \times 1.0) = 0.0 + 0.80 = 0.80$.
• Cosine Similarity 2 = $0.80 / (1.0 \times 1.0) = \mathbf{0.80}$.
3. Comparison:
Chunk 1 score (0.96) is higher than Chunk 2 score (0.80).
Final Answer: Similarity scores are 0.96 for Chunk 1 and 0.80 for Chunk 2. The system selects Chunk 1 as Top-1 candidate.
Problem 2: Reciprocal Rank Fusion (RRF) Ranking Calculation
Question: A hybrid search system evaluates a document chunk $D_A$ across sparse (BM25) and dense (vector) retrievers.
• $D_A$ is ranked #2 in Dense Search ($r_{\text{dense}} = 2$).
• $D_A$ is ranked #5 in Sparse BM25 Search ($r_{\text{sparse}} = 5$).
Using the standard RRF formula with smoothing constant $k = 60$:
$$\text{RRF\_Score}(D) = \sum_{m \in M} \frac{1}{k + r_m(D)}$$
Calculate the combined RRF score for document $D_A$.
Step-by-step Solution:
1. Compute term from Dense Search ($r_{\text{dense}} = 2$):
Term 1 = $1 / (60 + 2) = 1 / 62 \approx 0.016129$
2. Compute term from Sparse Search ($r_{\text{sparse}} = 5$):
Term 2 = $1 / (60 + 5) = 1 / 65 \approx 0.015385$
3. Sum RRF score terms:
RRF Score = $0.016129 + 0.015385 = \mathbf{0.031514}$
Final Answer: The combined Reciprocal Rank Fusion score for document $D_A$ is 0.031514.
Natural Language Processing & GenAI Sub-Cluster
-
Large Language Models & Transformers
Explore scaled attention mechanisms, GPT, LLaMA architectures, and autoregressive decoding. -
AI Agents & Autonomous Workflows
Explore ReAct agent loops, multi-agent orchestration, tool use, memory systems, and agent frameworks. -
Vector Databases & Semantic Search
Dive into dense embedding models, HNSW/IVF vector indexing, distance metrics, and hybrid search systems. -
Natural Language Processing Hub
Return to the main Natural Language Processing overview covering text preprocessing, tokenization, embeddings, and language models.
External Academic & Technical References
- Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks (Lewis et al., NeurIPS 2020) – The seminal paper introducing Retrieval-Augmented Generation architectures.
- Chain-of-Thought Prompting Elicits Reasoning in Large Language Models (Wei et al., NeurIPS 2022) – Foundational paper detailing step-by-step reasoning prompts in LLMs.
- ReAct: Synergizing Reasoning and Acting in Language Models (Yao et al., ICLR 2023) – Key research establishing dynamic reasoning and tool execution loops.