
The design of high-performing deep neural networks traditionally relied on tedious human trial-and-error, domain expertise, and manual hyperparameter tweaking. As neural network topologies evolved from simple multi-layer perceptrons to complex residual blocks, attention mechanisms, and vision transformers, manual design became an unsustainable engineering bottleneck. Automated Machine Learning (AutoML) and Neural Architecture Search (NAS) revolutionize model development by framing network design itself as an algorithmic optimization problem.
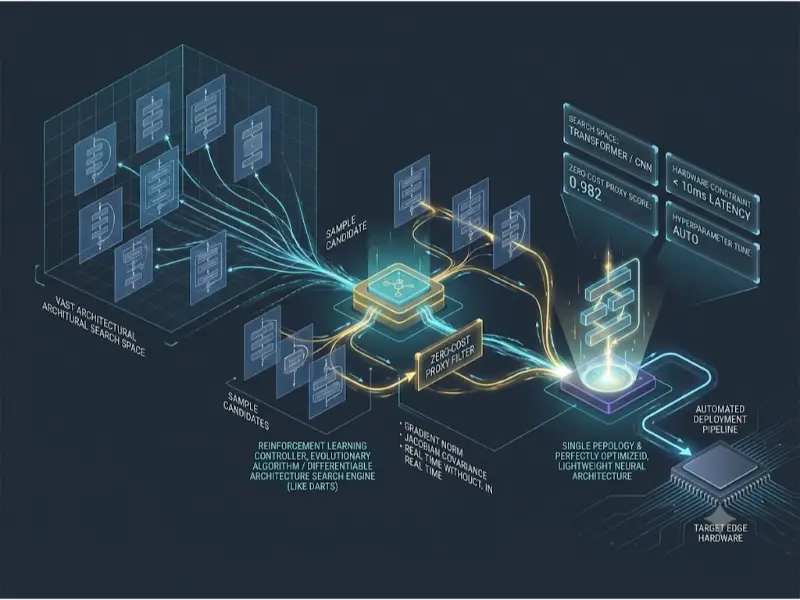
NAS automates the discovery of optimal network connectivity, layer operations, and cell topologies across a defined search space. By pairing search strategy controllers—such as Evolutionary Algorithms, Reinforcement Learning, or Differentiable Search (DARTS)—with fast evaluation proxies like Zero-Cost Proxies, AutoML systems discover architectures that routinely outperform human-designed baselines while optimizing strict hardware constraints like latency, memory footprint, and power consumption.
Interactive Quick Review: Search Space vs. Search Strategy
What is the fundamental difference between the “Search Space” and the “Search Strategy” in a Neural Architecture Search framework?Toggle Answer
Architectural & Theoretical Deep Dives
1. Discrete vs. Continuous Search Spaces (DARTS Mechanics)
Early NAS methods used discrete search spaces where a controller sampled complete candidate architectures, trained each candidate from scratch, and used validation accuracy as a reward signal. This required thousands of GPU hours. Differentiable Architecture Search (DARTS) addresses this computational bottleneck by relaxing the discrete choice of operations into a continuous, soft-max weighted mix.
Let O be a set of candidate operations (e.g., convolution, max pooling, identity) applied on node i to yield intermediate feature map x(j) at node j. The categorical choice is relaxed over operation weights α(i,j):
$$\bar{o}^{(i,j)}(x^{(i)}) = \sum_{o \in \mathcal{O}} \frac{\exp(\alpha_o^{(i,j)})}{\sum_{o’ \in \mathcal{O}} \exp(\alpha_{o’}^{(i,j)})} \, o(x^{(i)})$$This continuous formulation transforms architecture search into a bi-level optimization problem solved via gradient descent, jointly updating network weights w and architectural parameters α:
$$\min_\alpha L_{\text{val}}(w^*(\alpha), \alpha) \quad \text{s.t.} \quad w^*(\alpha) = \arg\min_w L_{\text{train}}(w, \alpha)$$2. Zero-Cost Proxies for Fast Performance Estimation
Evaluating candidate architectures by training them for multiple epochs remains extremely expensive. Zero-Cost Proxies estimate a candidate’s final accuracy at initialization (time t = 0) using a single forward/backward pass. Key zero-cost metrics include:
- synflow (Synaptic Flow): Measures conservation of synaptic score flow through weights to quantify network expressiveness and avoid layer collapse:$$\text{Score}_{\text{synflow}} = \sum_{l=1}^L \mathbf{1}^{\text{T}} \left| \frac{\partial R}{\partial \theta_l} \odot \theta_l \right| \mathbf{1}$$
- jacob_cov (Jacobian Covariance): Evaluates the correlation matrix of output gradients with respect to input data batches to assess linear separation capability prior to training.
3. Hardware-Aware Multi-Objective NAS
In real-world edge deployment, peak classification accuracy must be balanced against real-time latency, peak SRAM allocation, and battery wattage. Multi-objective NAS optimizes a Pareto frontier by evaluating a scalarized scalar objective or using Non-dominated Sorting Genetic Algorithms (NSGA-II):
$$\text{Objective}(\alpha) = \text{Accuracy}(\alpha) \times \left[ \frac{\text{Latency}(\alpha)}{\text{Target Latency}} \right]^\beta$$Where β is an exponent scalar parameter penalizing hardware constraint violations.
4. Python Implementation: Basic DARTS Softmax Operation Mixer
import torch

import torch.nn as nn

import torch.nn.functional as F


class MixedOp(nn.Module):

    """

    DARTS Mixed Operation layer relaxing discrete operation selection using continuous softmax parameters.

    """

    def __init__(self, C_in: int, C_out: int):

        super().__init__()

        self._ops = nn.ModuleList([

            nn.Conv2d(C_in, C_out, kernel_size=3, padding=1, bias=False),

            nn.Conv2d(C_in, C_out, kernel_size=5, padding=2, bias=False),

            nn.MaxPool2d(kernel_size=3, stride=1, padding=1),

            nn.Identity() if C_in == C_out else nn.Conv2d(C_in, C_out, 1, bias=False)

        ])


    def forward(self, x: torch.Tensor, weights: torch.Tensor):

        """

        weights: Architectural alpha parameters normalized via softmax (shape: [num_ops])

        """

        op_outputs = [op(x) for op in self._ops]

        return sum(w * op_out for w, op_out in zip(weights, op_outputs))


# Example setup

batch_x = torch.randn(2, 16, 32, 32)

mixed_layer = MixedOp(C_in=16, C_out=16)


# Raw unnormalized architectural parameters (alphas)

arch_alphas = torch.tensor([0.2, 1.5, -0.5, 0.1], requires_grad=True)

normalized_weights = F.softmax(arch_alphas, dim=-1)


output_tensor = mixed_layer(batch_x, normalized_weights)

print("Output Feature Map Shape:", output_tensor.shape)

print("Softmax Operation Weights:", normalized_weights.detach().numpy())
Interactive Quick Review: Performance Estimation Strategy
What is the main failure mode of Differentiable Architecture Search (DARTS), often referred to as “performance collapse”?Toggle Answer
Taxonomy & Optimization Comparison Matrix
| Search Paradigm | Search Cost (GPU Hours) | Search Space Flexibility | Hardware-Aware Optimization | Primary Advantage |
|---|---|---|---|---|
| Reinforcement Learning NAS (e.g., NASNet) | High (1,000–10,000 hrs) | Very High (Discrete tokens) | Yes (Reward penalty) | Discovers highly non-intuitive, innovative topologies |
| Evolutionary NAS (e.g., AmoebaNet) | High (2,000–3,000 hrs) | High (Graph mutations) | Yes (Multi-objective fitness) | Robust against local minima and optimization traps |
| Differentiable NAS (e.g., DARTS) | Low (< 10–24 hrs) | Moderate (Relaxed supernet) | Indirect (Loss terms) | Orders-of-magnitude faster gradient-based search |
| One-Shot / Weight-Sharing (e.g., Once-for-All) | Ultra-Low (Train supernet once) | High (Sub-network extraction) | Direct Lookup (Zero retraining) | Instantaneous deployment across diverse edge devices |
Applications, Trade-offs, & Future Outlook
Real-World Applications
- Edge ML Deployment (MobileNetV3 / EfficientNet): Designing specialized mobile vision models optimized for specific NPU hardware constraints (e.g., Qualcomm Hexagon, Apple Neural Engine).
- Automated Pipeline Generation (Auto-Sklearn / TPOT): End-to-end AutoML pipelines executing data preprocessing, feature selection, model choice, and hyperparameter tuning automatically.
- Transformer Architecture Search (HAT): Hardware-Aware Transformer discovery for optimizing LLM inference efficiency on edge microcontrollers and enterprise accelerators.
Engineering Trade-offs
While AutoML and NAS eliminate human design biases and produce state-of-the-art results, unconstrained search spaces can consume massive compute power and carbon footprints during supernet pre-training. Furthermore, architectures optimized using proxy tasks (e.g., searching on CIFAR-10) do not always scale linearly when transferred to massive datasets like ImageNet or multi-modal domains.
Future Outlook & Emerging Research
The frontier of NAS is moving toward Zero-Shot Architecture Search and LLM-Driven NAS. Rather than executing search algorithms over large supernets, pre-trained Large Language Models act as intelligent architectural mutation controllers, proposing optimized Python neural network structures based on plain-language system requirements.
Frequently Asked Questions
What is the difference between Hyperparameter Optimization (HPO) and NAS?
HPO optimizes scalar training configuration variables (e.g., learning rate, weight decay, batch size) for a fixed, existing neural network topology. NAS optimizes the structural connectivity, operator types, and layer arrangements of the neural network topology itself.What is a Supernet in One-Shot NAS?
A Supernet is an overarching network graph that encapsulates every candidate layer operation and connectivity path within its parameters. Candidate sub-networks inherit trained weight parameters directly from the Supernet, avoiding the need to train individual candidate models from scratch.How does Bayesian Optimization assist in AutoML?
Bayesian Optimization builds a probabilistic surrogate model (such as a Gaussian Process) of the objective function. It balances exploration (sampling uncertain regions) and exploitation (sampling regions known to yield high performance) using Acquisition Functions like Expected Improvement (EI).Why are Zero-Cost Proxies critical for sustainable AI research?
Traditional NAS requires thousands of GPU hours, creating massive carbon footprints and financial barriers. Zero-Cost Proxies estimate model performance in seconds using a single batch at initialization, reducing search compute budgets by over 99%.End-of-Page Exercises & Assessment
Part 1: Review Questions
Q1: Define the three core components of any Neural Architecture Search (NAS) framework.
Answer: The three core components are: 1. Search Space (the set of valid candidate architectures), 2. Search Strategy (the algorithm exploring the search space), and 3. Performance Estimation Strategy (the metric/method evaluating candidate performance).Q2: How does DARTS achieve continuous relaxation of discrete operation choices?
Answer: DARTS applies a continuous softmax function over continuous architecture parameters α assigned to each candidate operation, taking a weighted sum of all operation outputs rather than picking a single discrete operation.Q3: Explain the concept of a Pareto Frontier in Multi-Objective NAS.
Answer: The Pareto Frontier represents the set of optimal architectural candidates where no single metric (e.g., accuracy) can be improved without degrading another competing constraint (e.g., latency or energy consumption).Q4: What is the primary computational advantage of Once-for-All (OFA) weight-sharing?
Answer: OFA trains the supernet weights only once. Afterwards, customized sub-networks optimized for various hardware constraints can be extracted instantly via lookup without requiring retraining.Q5: Identify two zero-cost proxy metrics used for rapid performance estimation at initialization.
Answer: Synaptic Flow (synflow) and Jacobian Covariance (jacob_cov).Part 2: Thought-Provoking Questions
Q1: Human Expertise vs. Automated Topology Discovery
Scenario: An engineering team argues whether to manually adapt a vision transformer (ViT) architecture or deploy an automated NAS algorithm for an embedded edge camera. Analyze the engineering trade-offs.Analysis: Manual adaptation relies on established human design patterns and requires minimal upfront search compute, making it fast to deploy initially. However, human intuition frequently underestimates non-linear hardware bottlenecks (such as NPU memory cache paging). NAS explores non-intuitive layer dimensions and block pairings that maximize hardware utilization, yielding superior speed-accuracy trade-offs at the cost of upfront search compute.Q2: Overfitting the Search Space
Scenario: A search algorithm discovers an architecture that achieves 99.2% accuracy on a small validation set during proxy search, but performs worse than standard baselines when scaled to a full production dataset. Diagnose the failure mechanism.Analysis: This is an example of search-space overfitting (or proxy gap failure). When a proxy task is too small, unrepresentative, or evaluated for too few epochs, the search controller optimizes for artifacts specific to the proxy setup rather than generalizable representations. Resolving this requires cross-validation search folds, early-stopping regularization on architectural parameters (α), and robust zero-cost proxy metrics.End-of-Page Exercises & Assessment
Part 1: Review Questions
Q1: Define the three core components of any Neural Architecture Search (NAS) framework.
Answer: The three core components are: 1. Search Space (the set of valid candidate architectures), 2. Search Strategy (the algorithm exploring the search space), and 3. Performance Estimation Strategy (the metric/method evaluating candidate performance).
Q2: How does DARTS achieve continuous relaxation of discrete operation choices?
Answer: DARTS applies a continuous softmax function over continuous architecture parameters α assigned to each candidate operation, taking a weighted sum of all operation outputs rather than picking a single discrete operation.
Q3: Explain the concept of a Pareto Frontier in Multi-Objective NAS.
Answer: The Pareto Frontier represents the set of optimal architectural candidates where no single metric (e.g., accuracy) can be improved without degrading another competing constraint (e.g., latency or energy consumption).
Q4: What is the primary computational advantage of Once-for-All (OFA) weight-sharing?
Answer: OFA trains the supernet weights only once. Afterwards, customized sub-networks optimized for various hardware constraints can be extracted instantly via lookup without requiring retraining.
Q5: Identify two zero-cost proxy metrics used for rapid performance estimation at initialization.
Answer: Synaptic Flow (synflow) and Jacobian Covariance (jacob_cov).
Part 2: Thought-Provoking Questions
Q1: Human Expertise vs. Automated Topology Discovery
Scenario: An engineering team argues whether to manually adapt a vision transformer (ViT) architecture or deploy an automated NAS algorithm for an embedded edge camera. Analyze the engineering trade-offs.
Analysis: Manual adaptation relies on established human design patterns and requires minimal upfront search compute, making it fast to deploy initially. However, human intuition frequently underestimates non-linear hardware bottlenecks (such as NPU memory cache paging). NAS explores non-intuitive layer dimensions and block pairings that maximize hardware utilization, yielding superior speed-accuracy trade-offs at the cost of upfront search compute.
Q2: Overfitting the Search Space
Scenario: A search algorithm discovers an architecture that achieves 99.2% accuracy on a small validation set during proxy search, but performs worse than standard baselines when scaled to a full production dataset. Diagnose the failure mechanism.
Analysis: This is an example of search-space overfitting (or proxy gap failure). When a proxy task is too small, unrepresentative, or evaluated for too few epochs, the search controller optimizes for artifacts specific to the proxy setup rather than generalizable representations. Resolving this requires cross-validation search folds, early-stopping regularization on architectural parameters (α), and robust zero-cost proxy metrics.
Part 3: Numerical Engineering Problems
Problem 1: DARTS Softmax Operation Weight Calculation
Question: In a continuous DARTS edge, three candidate operations have unnormalized architectural parameters α1 = 1.2, α2 = 2.5, and α3 = 0.3.
1. Compute the softmax-normalized weight wi for each operation.
2. Given operation outputs o1(x) = 2.0, o2(x) = 5.0, and o3(x) = 1.0, calculate the combined output õ(x).
Step-by-step Solution:
1. Calculate exponentials (eαi):
• e1.2 ≈ 3.3201
• e2.5 ≈ 12.1825
• e0.3 ≈ 1.3499
• Sum = 3.3201 + 12.1825 + 1.3499 = 16.8525
2. Compute normalized weights (wi = eαi / Sum):
• w1 = 3.3201 / 16.8525 ≈ 0.1970
• w2 = 12.1825 / 16.8525 ≈ 0.7229
• w3 = 1.3499 / 16.8525 ≈ 0.0801
3. Compute combined output õ(x) = ∑ wi oi(x): $$\bar{o}(x) = (0.1970 \times 2.0) + (0.7229 \times 5.0) + (0.0801 \times 1.0)$$ $$\bar{o}(x) = 0.3940 + 3.6145 + 0.0801 = 4.0886$$
Final Answer: Weights are w1 ≈ 0.197, w2 ≈ 0.723, w3 ≈ 0.080, and the mixed output õ(x) ≈ 4.089.
Problem 2: Multi-Objective Hardware Score Optimization
Question: An AutoML controller evaluates two candidate models (Model A and Model B) against a latency constraint target Ltarget = 15.0 ms using the objective function:
$$\text{Score} = \text{Accuracy} \times \left[ \frac{\text{Latency}}{15.0} \right]^{-0.5}$$
Given:
• Model A: Accuracy = 82.0%, Latency = 10.0 ms
• Model B: Accuracy = 86.0%, Latency = 22.5 ms
Determine which model achieves the higher multi-objective score.
Step-by-step Solution:
1. Compute Score for Model A:
• Latency RatioA = 10.0 / 15.0 = 2/3 ≈ 0.6667
• Penalty FactorA = (0.6667)-0.5 = 1 / √(0.6667) ≈ 1.2247
• ScoreA = 82.0 × 1.2247 = 100.428
2. Compute Score for Model B:
• Latency RatioB = 22.5 / 15.0 = 1.5
• Penalty FactorB = (1.5)-0.5 = 1 / √(1.5) ≈ 0.8165
• ScoreB = 86.0 × 0.8165 = 70.219
Final Answer: Model A achieves a significantly higher score (100.43 vs. 70.22) because Model B is heavily penalized for violating the 15.0 ms latency target.
Advanced Neural Architectures Sub-Cluster
- Diffusion Models & GANsExplore Stable Diffusion, score-based generative architectures, and latent space diffusion mechanics.
- Efficient Deep Learning & QuantizationMaster model compression, INT8/FP4 quantization, channel pruning, and edge acceleration.
- Multimodal LearningDive into joint vision-language-audio representations, CLIP contrastive learning, and GPT-4o style systems.
External Academic & Technical References
- DARTS: Differentiable Architecture Search (Liu et al., ICLR 2019) – Foundational paper introducing continuous architecture relaxation via gradient descent.
- Once-for-All: Train One Network and Specialize it for Efficient Deployment (Cai et al., ICLR 2020) – Seminal work on weight-sharing supernets for hardware-aware deployment.
- Zero-Cost Proxies for Lightweight NAS (White et al., 2021) – Comprehensive survey and benchmark of zero-cost proxy metrics for ultra-fast architecture evaluation.