
A robotic system without control is merely an open-loop kinematic assembly of motors, gearboxes, and structural linkages. Actuators generate raw mechanical torque, but without carefully synthesized feedback loops, physical motion remains volatile, inaccurate, and susceptible to dynamic destabilization. Advanced control systems provide the analytical, state-space, and optimization frameworks that transform mechanical capability into deterministic, robust, and repeatable physical behavior.
In modern robotics, control systems regulate coupled multi-input multi-output (MIMO) physical quantities, including spatial joint trajectories, operational task-space wrenches, Cartesian impedance, and ground reaction forces. They guarantee that an articulated manipulator tracks dynamic setpoints without exciting structural resonances, that an autonomous vehicle maintains stability through nonholonomic maneuvers, and that physical disturbances—such as gear backlash, load variations, and contact friction—are rejected in real time.
Within the autonomous systems hierarchy, global and local motion planners answer where and how the robot should move in configuration space, while the control system determines how actuators generate voltages, currents, and torques to realize that motion under real-time determinism.
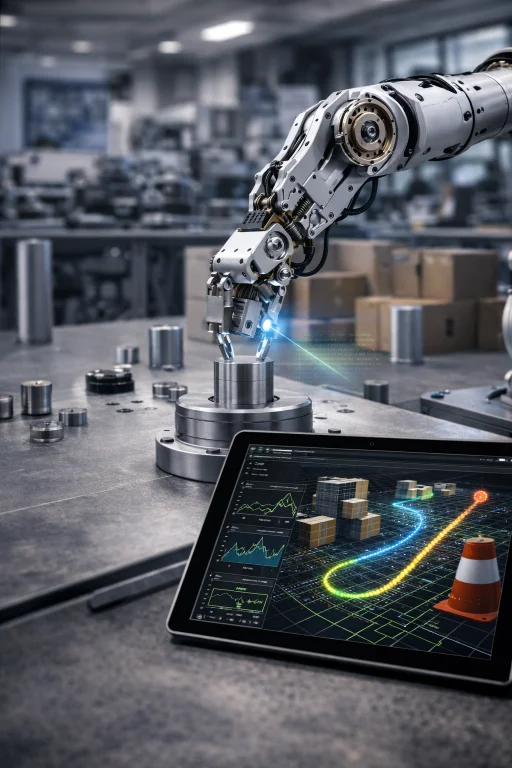
This visualization illustrates a closed-loop robotic control architecture executing precision manipulation. Embedded encoders and load cells stream real-time position and torque measurements into digital servo drives at multi-kilohertz sampling frequencies. The controller compares measured states against planned reference trajectories, dynamically generating corrective actuator voltages to counteract gravitational wrenches, inertial cross-coupling, and environmental contact forces.
Interactive Quick Review: Core Control Concepts
Test your understanding of open-loop versus closed-loop architectures and basic error tracking before exploring multi-variable state-space and optimal control strategies:
1. What is the fundamental operational difference between open-loop and closed-loop control systems?
Answer: Open-loop control commands actuators purely based on a pre-computed feedforward model without measuring the physical outcome, leaving the system vulnerable to drift and disturbances. Closed-loop control continuously samples output states via sensor feedback, computes the instantaneous tracking error \(e(t) = y_d(t) - y(t)\), and dynamically applies corrective inputs to drive error toward zero.
2. Within the standard robotic navigation pipeline, what is the division of labor between path planners and controllers?
Answer: Path planners evaluate environmental costmaps and kinematic constraints to construct a collision-free geometric reference trajectory in configuration space. Control systems execute downstream at much higher sampling frequencies (typically \(500\text{ Hz}\)–\(5\text{ kHz}\)), computing the precise actuator torques required to track that path while rejecting real-world friction, inertia, and external contact disturbances.
Open-Loop and Closed-Loop Control Paradigms
In physical robotics, control architectures are divided based on whether measured outputs influence future actuator commands:
- \(\mathbf{q}_d(t) \in \mathbb{R}^n\): Vector of desired joint positions over time.
- \(\mathbf{q}(t) \in \mathbb{R}^n\): Vector of measured actual joint positions.
- \(\mathbf{e}(t) = \mathbf{q}_d(t) - \mathbf{q}(t)\): Dynamic joint tracking error.
- \(\mathbf{u}(t) \in \mathbb{R}^n\): Actuator control inputs (e.g., motor phase currents or joint torques \(\boldsymbol{\tau}\)).
The primary design objective of asymptotic tracking control is to guarantee convergence of the error vector to the origin under bounded external perturbations:
$$\lim_{t \to \infty} \|\mathbf{e}(t)\| = 0 \quad \text{and} \quad \lim_{t \to \infty} \|\mathbf{\dot{e}}(t)\| = 0$$A direct-drive joint with torque constant \(K_t = 2.0\text{ Nm/A}\) is commanded via open-loop feedforward to rotate to \(\theta_d = 1.0\text{ rad}\) by applying a calibrated current pulse. Due to unmodeled static Coulomb friction \(\tau_{\text{fric}} = 0.16\text{ Nm}\), the joint stalls at \(\theta = 0.92\text{ rad}\).
Proportional–Integral–Derivative (PID) Control & Feedforward
The standard workhorse of industrial automation is the Proportional-Integral-Derivative (PID) control law, augmented with velocity and acceleration feedforward:
$$u(t) = K_P e(t) + K_I \int_0^t e(\tau) \, d\tau + K_D \frac{de(t)}{dt}$$- Proportional Gain (\(K_P\)): Provides an instantaneous restoring force proportional to displacement error, functioning as a virtual stiffness element.
- Integral Gain (\(K_I\)): Accumulates low-frequency residual error over time to overcome static friction, gravity sag, and parameter mismatches.
- Derivative Gain (\(K_D\)): Projects the future trajectory of the error state, injecting synthetic damping into the closed-loop system to suppress oscillations.
At sampling step \(k\), a joint controller evaluates instantaneous error \(e_k = 0.20\text{ rad}\), accumulated discrete error sum \(\sum e_i \Delta t = 0.50\text{ rad}\cdot\text{s}\), and numerical error derivative \(\Delta e / \Delta t = -0.10\text{ rad/s}\). Gains are tuned to \(K_P = 50\), \(K_I = 10\), and \(K_D = 5\).
State-Space Representation and Multi-Variable Analysis
Modern control methods model multi-degree-of-freedom robotic systems via first-order vector differential equations in state space:
$$\mathbf{\dot{x}}(t) = \mathbf{A}\mathbf{x}(t) + \mathbf{B}\mathbf{u}(t)$$ $$\mathbf{y}(t) = \mathbf{C}\mathbf{x}(t) + \mathbf{D}\mathbf{u}(t)$$For an articulated joint, the state vector typically packages generalized coordinates and velocities: \(\mathbf{x}(t) = \begin{bmatrix} q(t) & \dot{q}(t) \end{bmatrix}^T\). System stability is evaluated through the spectrum of system matrix \(\mathbf{A}\):
$$\det(\lambda \mathbf{I} - \mathbf{A}) = 0$$A continuous-time linear system is asymptotically stable if and only if all eigenvalues \(\lambda_i\) have strictly negative real parts: \(\text{Re}(\lambda_i) < 0, \forall i\).
Consider a linearized joint model with plant state matrix \(\mathbf{A} = \begin{bmatrix} 0 & 1 \\ -2 & -3 \end{bmatrix}\). Determine system stability.
Nonlinear Multi-Body Robot Dynamics
Rigid-body robotic manipulators operating across configuration space \(\mathbf{q} \in \mathbb{R}^n\) exhibit highly coupled, nonlinear dynamics derived via the Euler-Lagrange equations:
$$\mathbf{M}(\mathbf{q})\mathbf{\ddot{q}} + \mathbf{C}(\mathbf{q}, \mathbf{\dot{q}})\mathbf{\dot{q}} + \mathbf{g}(\mathbf{q}) = \boldsymbol{\tau} - \mathbf{J}^T(\mathbf{q})\mathbf{f}_{\text{ext}}$$- \(\mathbf{M}(\mathbf{q}) \in \mathbb{R}^{n \times n}\): Symmetric, positive-definite generalized mass/inertia matrix.
- \(\mathbf{C}(\mathbf{q}, \mathbf{\dot{q}}) \in \mathbb{R}^{n \times n}\): Coriolis and centrifugal wrench matrix, satisfying the skew-symmetry property \(\mathbf{z}^T (\mathbf{\dot{M}} - 2\mathbf{C}) \mathbf{z} = 0, \forall \mathbf{z}\).
- \(\mathbf{g}(\mathbf{q}) \in \mathbb{R}^n\): Vector of gravitational torques derived from potential energy: \(\mathbf{g}(\mathbf{q}) = \nabla_{\mathbf{q}} U(\mathbf{q})\).
- \(\mathbf{J}^T(\mathbf{q})\mathbf{f}_{\text{ext}}\): Reflected joint torques resulting from Cartesian environment contact wrenches \(\mathbf{f}_{\text{ext}}\).
Under Computed Torque Control (Feedback Linearization), the control law cancels physical nonlinearities using real-time dynamic inversion:
$$\boldsymbol{\tau} = \mathbf{M}(\mathbf{q})\left[\mathbf{\ddot{q}}_d + \mathbf{K}_D(\mathbf{\dot{q}}_d - \mathbf{\dot{q}}) + \mathbf{K}_P(\mathbf{q}_d - \mathbf{q})\right] + \mathbf{C}(\mathbf{q}, \mathbf{\dot{q}})\mathbf{\dot{q}} + \mathbf{g}(\mathbf{q})$$Substituting this control law into the equations of motion decouples the robot into \(n\) independent linear second-order error systems: \(\mathbf{\ddot{e}} + \mathbf{K}_D \mathbf{\dot{e}} + \mathbf{K}_P \mathbf{e} = \mathbf{0}\).
Linear Quadratic Regulator (LQR) Optimal Control
Optimal control calculates feedback gains that minimize a balance between state tracking error and actuator control expenditure over an infinite horizon:
$$J = \int_0^\infty \left(\mathbf{x}^T \mathbf{Q} \mathbf{x} + \mathbf{u}^T \mathbf{R} \mathbf{u}\right) dt$$Where \(\mathbf{Q} \succeq 0\) is a symmetric positive semi-definite state penalty matrix, and \(\mathbf{R} \succ 0\) is a symmetric positive-definite control effort penalty matrix. The optimal state-feedback control law is:
$$\mathbf{u} = -\mathbf{K}\mathbf{x} = -\mathbf{R}^{-1}\mathbf{B}^T \mathbf{P} \mathbf{x}$$Where the symmetric positive-definite matrix \(\mathbf{P}\) is the unique solution to the Continuous-Time Algebraic Riccati Equation (CARE):
$$\mathbf{A}^T \mathbf{P} + \mathbf{P}\mathbf{A} - \mathbf{P}\mathbf{B}\mathbf{R}^{-1}\mathbf{B}^T \mathbf{P} + \mathbf{Q} = \mathbf{0}$$Lyapunov Stability Analysis
Lyapunov theory provides a mathematical foundation for certifying asymptotic stability in nonlinear robotic systems without requiring explicit analytical solutions to differential equations.
Let \(\mathbf{x} = \mathbf{0}\) be an equilibrium state of the autonomous system \(\mathbf{\dot{x}} = \mathbf{f}(\mathbf{x})\). A scalar energy-like function \(V(\mathbf{x}): \mathbb{R}^n \to \mathbb{R}\) is a Lyapunov candidate function if:
- \(V(\mathbf{0}) = 0\).
- \(V(\mathbf{x}) > 0, \quad \forall \mathbf{x} \neq \mathbf{0}\) (Locally positive definite).
- \(\dot{V}(\mathbf{x}) = \nabla V(\mathbf{x})^T \mathbf{f}(\mathbf{x}) \le 0\) (Negative semi-definite).
If \(\dot{V}(\mathbf{x}) < 0, \forall \mathbf{x} \neq \mathbf{0}\) (strictly negative definite), the origin is asymptotically stable. If \(V(\mathbf{x})\) is radially unbounded (\(V(\mathbf{x}) \to \infty\) as \(\|\mathbf{x}\| \to \infty\)), the equilibrium is globally asymptotically stable.
Model Predictive Control (MPC)
Model Predictive Control solves a constrained dynamic optimization problem online over a finite predictive horizon of \(N\) steps. At time step \(k\), the controller solves for the optimal sequence of control actions:
$$\min_{\mathbf{u}_0, \dots, \mathbf{u}_{N-1}} \sum_{j=0}^{N-1} \left(\mathbf{x}_{k+j|k}^T \mathbf{Q} \mathbf{x}_{k+j|k} + \mathbf{u}_{k+j|k}^T \mathbf{R} \mathbf{u}_{k+j|k}\right) + \mathbf{x}_{k+N|k}^T \mathbf{P}_f \mathbf{x}_{k+N|k}$$Subject to discrete system dynamics and operational physical constraints:
$$\mathbf{x}_{k+j+1|k} = \mathbf{A}_d \mathbf{x}_{k+j|k} + \mathbf{B}_d \mathbf{u}_{k+j|k}$$ $$\mathbf{u}_{\min} \le \mathbf{u}_{k+j|k} \le \mathbf{u}_{\max}$$ $$\mathbf{x}_{\min} \le \mathbf{x}_{k+j|k} \le \mathbf{x}_{\max}$$Applying the receding horizon principle, only the first control vector \(\mathbf{u}_k^* = \mathbf{u}_{0|k}^*\) is transmitted to the motor drives. At step \(k+1\), the horizon advances, the state estimate updates from sensors, and the optimization problem re-executes.
Control Engineering Challenges and Technical Solutions
Translating theoretical control algorithms onto real-world embedded robotic platforms introduces fundamental physical bottlenecks. Below are four primary engineering challenges and the mechatronic techniques developed to overcome them:
The Challenge: High-ratio gear transmissions exhibit complex friction nonlinearities, including static breakaway stiction, velocity-dependent Stribeck friction, and hysteresis. Traditional linear controllers treat friction as simple viscous damping, resulting in steady-state limit cycles, tracking deadbands, and joint velocity reversal lag.
Technical Solutions:
- Dynamic Friction Observers (LuGre & Dahl Models): Integrating microscopic bristle-deflection friction observers within the feedforward controller to cancel breakaway torque proactively prior to macroscopic joint displacement.
- Sliding Mode Disturbance Observers: Utilizing discontinuous switching functions \(\tau_{\text{comp}} = \rho \cdot \text{sgn}(s)\) along an error sliding manifold to guarantee invariance against bounded unmodeled friction torques.
- Dither Injection: Injecting high-frequency, low-amplitude torque dither signals outside the robot's physical structural bandwidth to maintain bearings in continuous kinetic sliding, suppressing static friction traps.
The Challenge: Nonlinear Model Predictive Control (NMPC) and whole-body optimization require solving large quadratic programs (QP) within strict real-time deadlines (\(1\text{ ms}\) for bipedal balancing; \(250\text{ }\mu\text{s}\) for industrial arms). Solver timeout or computational jitter can cause servo instability and catastrophic trajectory divergence.
Technical Solutions:
- Real-Time Iteration (RTI) Schemes: Decoupling the MPC loop into an asynchronous preparation phase (linearizing system dynamics offline) and an ultra-fast feedback phase (solving a single condensed QP step in microseconds upon receiving fresh state feedback).
- GPU-Accelerated Operator Splitting (OSQP / HPIPM): Deploying parallel alternating direction method of multipliers (ADMM) solvers optimized on embedded tensor cores to solve multi-contact dynamics in real time.
- Warm-Starting and Policy Surrogates: Initializing primal-dual interior-point solvers using trajectory shifts from the previous sampling instant, or utilizing deep neural networks as near-optimal warm-start seeds.
The Challenge: Vision systems, LiDARs, and networked CAN-FD/EtherCAT buses introduce processing latencies and transport jitter ranging from \(5\text{ ms}\) to \(50\text{ ms}\). Feeding delayed state measurements into high-gain controllers introduces phase lag that erodes the phase margin, triggering high-frequency hunting and instability.
Technical Solutions:
- Unscented / Extended Kalman Filtering with Out-of-Sequence Updates: Running high-rate (\(1\text{ kHz}\)) IMU kinematic propagation while fusing delayed exteroceptive vision packets via retroactive buffer rewinding and factor-graph smoothing.
- Smith Predictor Architectures: Utilizing an internal dynamic plant model to simulate immediate state responses, canceling pure transport dead-time from the primary feedback loop.
- Deterministic Real-Time Ethernet Protocols: Synchronizing distributed actuator nodes using IEEE 802.1AS Precision Time Protocol (PTP) and EtherCAT distributed clocks to constrain hardware jitter below \(1\text{ }\mu\text{s}\).
The Challenge: To optimize payload-to-weight ratios, robotic links are constructed from lightweight materials that flex under high angular accelerations. High-gain feedback loops inadvertently inject energy into structural resonant modes, producing severe end-effector vibrations and risking structural fatigue.
Technical Solutions:
- Input Shaping and Resonant Notch Filters: Filtering reference trajectory setpoints through Zero-Vibration (ZV) or Zero-Vibration-Derivative (ZVD) impulse convolving sequences, guaranteeing zero spectral energy at structural modal frequencies.
- Singular Perturbation Flexible-Joint Control: Partitioning joint dynamics into fast motor rotor coordinates and slow elastic link coordinates, utilizing active joint torque feedback loops to inject virtual damping into the flexural modes.
- Active Disturbance Rejection Control (ADRC): Lumping structural unmodeled dynamics and external load shocks into a total disturbance state, estimating and canceling it in real time via an Extended State Observer (ESO).
🎯 Career Guidance Tool Is Robotics Control Systems Engineering Right For You?Explore control theory pathways, evaluate your mathematical fit, and map your trajectory into physical AI and autonomous motion control. | Explore Career Options → |
Interactive Quick Review: Advanced Control & Optimization
Reinforce core principles regarding integral reset windup, state-space constraints, and optimization matrices before exploring the FAQ:
1. What is integrator windup in PID controllers and how is it mitigated?
Answer: Integrator windup occurs when actuator torque saturates (e.g., reaching maximum motor current limits); the integral term continues accumulating error, causing large overshoot and recovery delays once the error changes sign. It is mitigated using anti-windup clamping schemes or back-calculation tracking circuits that halt integration whenever saturation flags trigger.
2. How does Model Predictive Control (MPC) handle physical constraints compared to LQR?
Answer: LQR computes an unconstrained analytical gain matrix that assumes infinite actuator authority. Model Predictive Control incorporates hard inequality constraints on actuator torque, velocity limits, and Cartesian obstacle avoidance boundaries directly into its online quadratic program, solving for feasible inputs at every sampling step.
Frequently Asked Questions
What is an advanced control system in robotics, and why is it necessary?
An advanced control system consists of mathematical algorithms and closed-loop feedback laws that compute motor inputs to enforce precise physical motion. It is indispensable because real-world robots are subject to gravity, multi-axis Coriolis cross-coupling, friction, and environmental contact forces that destabilize unguided open-loop commands.
How do PID controllers differ from modern optimal control techniques like LQR or MPC?
PID controllers react to historical, present, and derivative error signals on single input-output loops without requiring an analytical dynamic model of the plant. In contrast, LQR and Model Predictive Control exploit comprehensive multi-variable state-space models and numerical optimization to balance trajectory precision against actuator energy consumption while respecting operational constraints.
What role does mathematics play in studying control systems at university?
Mathematics is the analytical engine of control theory. Engineers utilize linear algebra for state-space transformations and eigenvalue placement, multi-variable differential equations for Newtonian dynamics, complex analysis and Laplace transforms for frequency-domain stability, and convex optimization for real-time MPC quadratic programming.
How does stability analysis ensure safety in robotic applications?
Stability analysis, using tools such as Lyapunov energy dissipation theorems and Routh-Hurwitz criteria, mathematically proves that tracking errors are guaranteed to converge to bounded sets rather than grow exponentially. This prevents physical runaway, harmonic actuator damage, and hazardous collisions in collaborative settings.
End-of-Page Exercises: Review, Thought-Provoking & Engineering Problems
Section 1: Foundational Review Questions & Answers
1. What is the fundamental difference between open-loop and closed-loop control systems?
Answer: Open-loop control commands actuators without feedback verification. Closed-loop control continuously measures output states via sensors, calculates tracking error, and applies corrective control signals in real time.
2. What are the respective roles of the proportional (\(K_P\)), integral (\(K_I\)), and derivative (\(K_D\)) gains in a PID controller?
Answer: \(K_P\) delivers a restoring command proportional to present error; \(K_I\) accumulates past error over time to eliminate steady-state offset; \(K_D\) dampens the response based on the rate of error change to prevent excessive overshoot.
3. How are dynamic systems represented in modern control theory using state-space equations?
Answer: State-space models express dynamic systems through coupled first-order vector differential equations: \(\mathbf{\dot{x}}(t) = \mathbf{A}\mathbf{x}(t) + \mathbf{B}\mathbf{u}(t)\) for internal state propagation, and \(\mathbf{y}(t) = \mathbf{C}\mathbf{x}(t) + \mathbf{D}\mathbf{u}(t)\) for observed algebraic outputs.
4. What determines the stability of a linear time-invariant (LTI) state-space system?
Answer: Asymptotic stability is determined by the eigenvalues of system matrix \(\mathbf{A}\). The system is stable if and only if every eigenvalue possesses a strictly negative real part: \(\text{Re}(\lambda_i) < 0\).
5. What physical quantities do matrices \(\mathbf{M}(\mathbf{q})\), \(\mathbf{C}(\mathbf{q}, \mathbf{\dot{q}})\), and \(\mathbf{g}(\mathbf{q})\) represent in manipulator dynamics?
Answer: \(\mathbf{M}(\mathbf{q})\) is the configuration-dependent symmetric inertia matrix; \(\mathbf{C}(\mathbf{q}, \mathbf{\dot{q}})\) captures velocity-squared Coriolis and centrifugal cross-coupling forces; \(\mathbf{g}(\mathbf{q})\) represents configuration-dependent gravitational torques.
6. How does a Linear Quadratic Regulator (LQR) compute an optimal control law?
Answer: LQR minimizes an infinite-horizon quadratic cost function weighting state error against control effort. Solving the Algebraic Riccati Equation yields a static optimal gain matrix \(\mathbf{K}\) such that \(\mathbf{u} = -\mathbf{K}\mathbf{x}\).
7. What is the fundamental principle behind Lyapunov stability analysis?
Answer: If an energy-like scalar function \(V(\mathbf{x})\) is positive definite and its continuous time derivative \(\dot{V}(\mathbf{x})\) is strictly negative definite, system energy dissipates continuously, guaranteeing asymptotic convergence to the origin.
8. What key advantage does Model Predictive Control (MPC) offer over traditional feedback controllers?
Answer: MPC optimizes future trajectories over a finite moving horizon while explicitly enforcing hard inequality constraints on actuator torque limits, velocity boundaries, and obstacle avoidance envelopes.
9. Why do standard wheeled mobile robots exhibit nonholonomic motion constraints?
Answer: Wheeled mobile robots are governed by non-integrable velocity constraints: the no-slip condition prevents instantaneous lateral motion (\(\dot{y} \cos\theta - \dot{x} \sin\theta = 0\)), restricting instantaneous velocity degrees of freedom below total configuration coordinates.
10. What is the operational purpose of state estimators such as Kalman filters in control loops?
Answer: State estimators fuse uncertain plant dynamic models with noisy, delayed sensor measurements to generate statistically optimal, real-time estimates of unmeasured state variables (such as link velocities or joint accelerations).
Section 2: Analytical & Thought-Provoking Questions
1. How do unmodeled structural resonances in flexible robot links compromise closed-loop stability?
Answer: High-bandwidth controllers inadvertently inject control energy into the high-frequency flexural modes of lightweight links. The resulting structural vibration introduces significant phase lag, converting negative feedback into positive feedback and causing destructive mechanical resonance.
2. What are the computational challenges of deploying Model Predictive Control (MPC) on high-DOF humanoids?
Answer: Humanoids feature high-dimensional state spaces (\(30+\) active joints) and non-smooth contact mechanics with the floor. Solving nonlinear complementarity quadratic programs across multi-second prediction horizons within sub-millisecond servo loops strains onboard embedded processors, necessitating specialized GPU solvers and reduced-order centroidal dynamics.
3. How does data-driven reinforcement learning challenge traditional proof-based stability guarantees?
Answer: Classical control theory provides analytical Lyapunov stability margins and gain guarantees. Deep RL policies are parameterized by high-dimensional, non-convex neural networks whose boundary behaviors under out-of-distribution physical shocks cannot be readily certified, creating safety risks in physical deployments.
4. In safety-critical surgical robotics, how do control systems guarantee fail-safe behavior during hardware sensor drops?
Answer: Surgical systems implement triple-modular redundant encoders, hardware watchdog monitors, and analytical disturbance observers. When sensor invalidity is flagged, the controller freezes the active tool position, smoothly ramps down motor currents, and transfers control to mechanical fail-safe brakes in under \(5\text{ ms}\).
5. How do variable stiffness actuators blur the boundary between mechanical design and control theory?
Answer: Instead of treating compliance as an undesirable structural flaw, variable stiffness actuators (VSAs) treat joint stiffness as an active state variable. The controller dynamically shifts physical joint compliance to store energy during cyclic locomotion or soften during human impact.
6. What limitations arise when applying linear control theory to articulated robots operating across vast workspaces?
Answer: A robotic manipulator's effective inertia matrix and gravitational loading vary dramatically depending on link posture. A linear controller tuned for a compact configuration becomes sluggish, under-damped, or unstable when the arm fully extends, highlighting the necessity of nonlinear feedback linearization.
7. How can adaptive control laws maintain trajectory tracking when an arm grasps an unknown payload mass?
Answer: Adaptive controllers utilize regressor matrices \(\mathbf{Y}(\mathbf{q}, \mathbf{\dot{q}}, \mathbf{\ddot{q}})\) to parameterize physical dynamics linearly with respect to unknown parameters. Online parameter adaptation laws update mass and inertia estimates in real time, driving tracking error asymptotically to zero.
8. What ethical and legal questions emerge if an autonomous vehicle's predictive controller chooses between collision profiles?
Answer: Predictive controllers minimize cost functions that weigh obstacle clearance, deceleration forces, and collision probabilities. Mathematically assigning numeric penalty weights to different collision scenarios formalizes moral trade-offs, raising fundamental questions regarding developer liability and algorithmic ethics.
9. How does time delay in networked cloud robotics degrade closed-loop stabilization loops?
Answer: Network transmission latency introduces non-minimum phase dead-time \(e^{-sT}\) into the loop transfer function, causing substantial phase lag. If loop gain is high, phase margin drops below zero, triggering severe limit-cycle oscillations and destabilization.
10. How do sliding mode controllers achieve high robustness against unmodeled plant disturbances?
Answer: Sliding mode control drives system states toward a sliding surface \(s(\mathbf{e}) = \mathbf{0}\) using high-frequency discontinuous feedback. Once on the manifold, system dynamics depend entirely on chosen sliding surface parameters, rendering the response invariant to matched parameter variations and external disturbance forces.
11. In multi-robot swarms, how do decentralized local consensus laws generate global flocking behaviors?
Answer: Swarm consensus algorithms use Laplacian graph theory to enforce local neighbor agreement: \(\mathbf{\dot{x}}_i = -\sum_{j \in \mathcal{N}_i} a_{ij}(\mathbf{x}_i - \mathbf{x}_j)\). By coupling local velocity matching, separation gradients, and cohesion, complex collective macro-behaviors emerge without centralized coordination.
12. What distinguishes Active Disturbance Rejection Control (ADRC) from traditional disturbance observers?
Answer: ADRC treats all unmodeled internal dynamics, friction nonlinearities, and external disturbances as an augmented generalized state variable. An Extended State Observer (ESO) estimates this total disturbance in real time, canceling it without requiring an explicit mathematical plant model.
Section 3: Numerical Engineering Problems & Solutions
A robotic joint controller uses a PID algorithm with gains \(K_P = 40\text{ Nm/rad}\), \(K_I = 5\text{ Nm/(rad}\cdot\text{s)}\), and \(K_D = 2\text{ Nm}\cdot\text{s/rad}\). At a sampling instant, instantaneous tracking error is \(e(t) = 0.15\text{ rad}\), accumulated integral error is \(\int_0^t e(\tau)d\tau = 0.40\text{ rad}\cdot\text{s}\), and error derivative is \(\dot{e}(t) = -0.05\text{ rad/s}\). Calculate the total control command output \(u(t)\).
Continuous-time PID equation: $$u(t) = K_P e(t) + K_I \int_0^t e(\tau)d\tau + K_D \frac{de(t)}{dt}$$ Substitute numerical values: $$u_P = 40 \times 0.15 = 6.0\text{ Nm}$$ $$u_I = 5 \times 0.40 = 2.0\text{ Nm}$$ $$u_D = 2 \times (-0.05) = -0.10\text{ Nm}$$ Summing the control terms: $$u(t) = 6.0 + 2.0 - 0.10 = 7.90\text{ Nm}$$ Final Answer: Total control command output is \(7.90\text{ Nm}\).
A linear time-invariant robotic system is described by state matrix \(\mathbf{A} = \begin{bmatrix} 0 & 1 \\ -4 & -5 \end{bmatrix}\). Determine the characteristic equation and calculate system eigenvalues to assess stability.
Evaluate the characteristic determinant: $$\det(\lambda\mathbf{I} - \mathbf{A}) = \det \begin{bmatrix} \lambda & -1 \\ 4 & \lambda + 5 \end{bmatrix} = \lambda(\lambda + 5) - (-1)(4) = 0$$ $$\lambda^2 + 5\lambda + 4 = 0$$ Factor the characteristic equation: $$(\lambda + 1)(\lambda + 4) = 0 \Rightarrow \lambda_1 = -1.0, \quad \lambda_2 = -4.0$$ Final Answer: Eigenvalues are \(\lambda_1 = -1.0\) and \(\lambda_2 = -4.0\). Because both roots have strictly negative real parts, the system is asymptotically stable.
A discrete-time state update equation is given by \(x_{k+1} = A_d x_k + B_d u_k\), where \(A_d = 0.85\), \(B_d = 0.15\), and constant control input is \(u_k = -2.0\). Given initial state \(x_0 = 4.0\), calculate state values \(x_1\) and \(x_2\).
Calculate state at step 1: $$x_1 = A_d x_0 + B_d u_0 = (0.85 \times 4.0) + (0.15 \times -2.0) = 3.40 - 0.30 = 3.10$$ Calculate state at step 2: $$x_2 = A_d x_1 + B_d u_1 = (0.85 \times 3.10) + (0.15 \times -2.0) = 2.635 - 0.30 = 2.335$$ Final Answer: States are \(x_1 = 3.10\) and \(x_2 = 2.335\).
Consider the scalar nonlinear autonomous system \(\dot{x} = -2x^3\). Using the Lyapunov candidate function \(V(x) = \frac{1}{2} x^2\), compute its continuous time derivative \(\dot{V}(x)\) and prove asymptotic stability of the origin.
Verify \(V(x)\) is positive definite: \(V(0) = 0\) and \(V(x) > 0\) for all \(x \neq 0\).
Differentiate \(V(x)\) with respect to time along system trajectories: $$\dot{V}(x) = \frac{\partial V}{\partial x} \dot{x} = x \cdot \dot{x}$$ Substitute the system dynamics \(\dot{x} = -2x^3\): $$\dot{V}(x) = x(-2x^3) = -2x^4$$ Analyze sign definiteness: For all \(x \neq 0\), \(x^4 > 0\), which implies: $$\dot{V}(x) = -2x^4 < 0 \quad (\text{Strictly negative definite})$$ Final Answer: Since \(V(x)\) is positive definite and radially unbounded, and \(\dot{V}(x)\) is strictly negative definite, the origin is globally asymptotically stable.
A robotic joint system has instantaneous state vector \(\mathbf{x} = \begin{bmatrix} 0.50 & -0.10 \end{bmatrix}^T\). Linear Quadratic Regulator optimization yields the optimal state-feedback gain matrix \(\mathbf{K} = \begin{bmatrix} 12.0 & 3.5 \end{bmatrix}\). Calculate the optimal control command \(u\).
LQR state-feedback control law: $$u = -\mathbf{K}\mathbf{x} = -\begin{bmatrix} 12.0 & 3.5 \end{bmatrix} \begin{bmatrix} 0.50 \\ -0.10 \end{bmatrix}$$ Execute vector dot product: $$u = -\left[(12.0 \times 0.50) + (3.5 \times -0.10)\right] = -\left[6.0 - 0.35\right] = -5.65$$ Final Answer: Optimal control command is \(u = -5.65\).
An MPC controller computes an unconstrained optimal control command of \(u_{\text{raw}} = 14.2\text{ Nm}\). The joint actuator hardware is bounded by strict physical saturation limits \(u_{\max} = 10.0\text{ Nm}\) and \(u_{\min} = -10.0\text{ Nm}\). Determine the actual control input delivered to the joint.
Apply the saturation projection operator: $$u_{\text{actual}} = \text{sat}(u_{\text{raw}}) = \min\left(\max(u_{\text{raw}}, u_{\min}), u_{\max}\right)$$ Substitute numerical values: $$u_{\text{actual}} = \min\left(\max(14.2, -10.0), 10.0\right) = \min(14.2, 10.0) = 10.0\text{ Nm}$$ Final Answer: The saturated input delivered to the motor is \(10.0\text{ Nm}\).
A differential-drive autonomous mobile robot moves with forward linear chassis velocity \(v = 0.80\text{ m/s}\) and angular steering yaw rate \(\omega = 0.50\text{ rad/s}\). Calculate the instantaneous turning radius \(R\) of the robot's trajectory.
Differential kinematics turning radius formulation: $$R = \frac{v}{\omega}$$ Substitute values: $$R = \frac{0.80\text{ m/s}}{0.50\text{ rad/s}} = 1.60\text{ meters}$$ Final Answer: Instantaneous turning radius is \(1.60\text{ meters}\).
A discrete Kalman filter predicts an a priori joint angle estimate of \(\hat{x}_{k|k-1} = 1.20\text{ rad}\). A noisy optical encoder measurement reads \(z_k = 1.28\text{ rad}\). If the computed optimal Kalman gain is \(K_k = 0.40\) (with observation matrix \(H = 1\)), calculate the updated a posteriori state estimate \(\hat{x}_{k|k}\).
Kalman filter measurement correction formulation: $$\hat{x}_{k|k} = \hat{x}_{k|k-1} + K_k \left(z_k - H \hat{x}_{k|k-1}\right)$$ Compute innovation residual: $$\tilde{y}_k = z_k - H \hat{x}_{k|k-1} = 1.28 - (1 \times 1.20) = 0.08\text{ rad}$$ Apply the Kalman gain: $$\hat{x}_{k|k} = 1.20 + 0.40(0.08) = 1.20 + 0.032 = 1.232\text{ rad}$$ Final Answer: Updated posterior state estimate is \(1.232\text{ rad}\).
An embedded robotic servo controller runs at a discrete sampling frequency of \(f_s = 1{,}000\text{ Hz}\). Calculate the discrete sampling period \(T_s\) in milliseconds, and compute the maximum recommended closed-loop tracking bandwidth \(f_c\) using the standard empirical design guideline (\(f_c \le 0.1 \times f_s\)).
Sampling period: $$T_s = \frac{1}{f_s} = \frac{1}{1000\text{ Hz}} = 0.001\text{ s} = 1.0\text{ ms}$$ Maximum recommended closed-loop bandwidth: $$f_c = 0.1 \times f_s = 0.1 \times 1000\text{ Hz} = 100.0\text{ Hz}$$ Final Answer: Sampling interval is \(1.0\text{ ms}\); maximum recommended bandwidth is \(100.0\text{ Hz}\).
A single-link rigid arm of mass \(m = 4.0\text{ kg}\) has its center of mass located at distance \(l_c = 0.30\text{ m}\) from the joint axis, operating under gravitational acceleration \(g = 9.81\text{ m/s}^2\). Calculate the feedforward gravity compensation torque \(\tau_G\) required to hold the link stationary at angle \(\theta = 60^\circ\) relative to the vertical downward axis. (Use \(\sin(60^\circ) = 0.866\)).
Gravitational torque formulation: $$\tau_G = m \cdot g \cdot l_c \cdot \sin(\theta)$$ Substitute numerical values: $$\tau_G = 4.0\text{ kg} \times 9.81\text{ m/s}^2 \times 0.30\text{ m} \times 0.866$$ $$\tau_G = 39.24 \times 0.30 \times 0.866 = 11.772 \times 0.866 \approx 10.1945\text{ Nm}$$ Final Answer: Required feedforward holding torque is approximately \(10.19\text{ Nm}\).
An RTOS executes three periodic control tasks:
- Task 1 (Inner Current Loop): \(C_1 = 1.0\text{ ms}, T_1 = 5.0\text{ ms}\)
- Task 2 (Velocity Loop): \(C_2 = 2.0\text{ ms}, T_2 = 10.0\text{ ms}\)
- Task 3 (Trajectory Generation): \(C_3 = 3.0\text{ ms}, T_3 = 20.0\text{ ms}\)
Compute task utilization ratios: $$U_1 = \frac{C_1}{T_1} = \frac{1.0}{5.0} = 0.20$$ $$U_2 = \frac{C_2}{T_2} = \frac{2.0}{10.0} = 0.20$$ $$U_3 = \frac{C_3}{T_3} = \frac{3.0}{20.0} = 0.15$$ Calculate cumulative CPU utilization: $$U = U_1 + U_2 + U_3 = 0.20 + 0.20 + 0.15 = 0.55 \Rightarrow 55\%$$ Compare against theoretical bound: $$U = 0.55 \le U_{\text{bound}} \approx 0.780$$ Final Answer: Total processor utilization is \(55\%\). Because \(U \le 0.780\), the real-time control task set is guaranteed schedulable under Rate Monotonic Scheduling.
A robotic servo drive is modeled as a first-order lag filter with corner frequency \(f_c = 50.0\text{ Hz}\). Compute the system time constant \(\tau = \frac{1}{2\pi f_c}\), and calculate the output phase lag in degrees when tracking a sinusoidal trajectory at frequency \(f = 25.0\text{ Hz}\).
Calculate time constant: $$\tau = \frac{1}{2\pi \times 50.0} = \frac{1}{314.159} \approx 0.003183\text{ s} = 3.183\text{ ms}$$ Compute angular frequency parameter at \(f = 25.0\text{ Hz}\): $$\omega = 2\pi f = 2\pi \times 25.0 = 157.08\text{ rad/s}$$ $$\omega\tau = 157.08 \times 0.003183 \approx 0.500$$ Evaluate phase angle: $$\phi = -\arctan(\omega\tau) = -\arctan(0.500) \approx -0.46365\text{ rad}$$ Convert to degrees: $$\phi_{\text{deg}} = -0.46365 \times \left(\frac{180^\circ}{\pi}\right) \approx -26.565^\circ$$ Final Answer: Time constant is \(\tau = 3.18\text{ ms}\); output phase lag at \(25\text{ Hz}\) is approximately \(-26.57^\circ\).
Advanced Control Systems — Summary & Wrap-Up
Control systems provide the mathematical bridge between raw physical actuation and intelligent robotic autonomy. By synthesizing feedback linearization, multi-variable state-space modeling, Lyapunov stability verification, and real-time Model Predictive Control, control engineers design robust platforms capable of executing agile trajectories, rejecting high-entropy environmental disturbances, and guaranteeing absolute physical safety across industrial, surgical, and autonomous vehicular operations.